← Back to project

1 · Box tracker: design, training and final evaluation

Stage 1 · mechanism, training recipe and selected full-validation result
2D trackingbox memoryselected checkpoint

Current project overview

Selected result

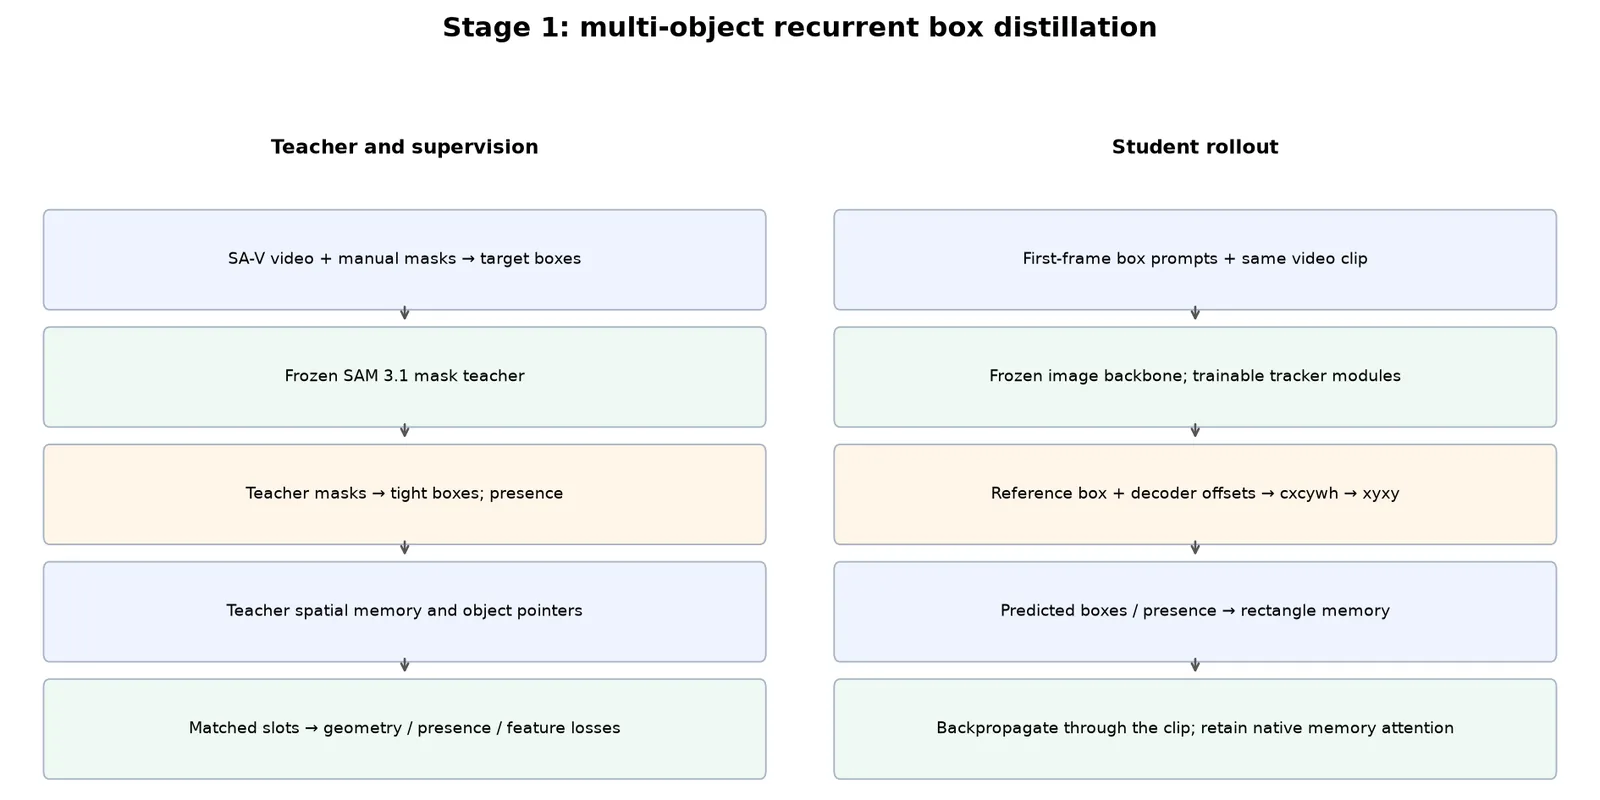
Stage 1 delivers a 2D multi-object box tracker with recurrent box memory. The selected inference policy preserves the last valid reference when an object is absent.
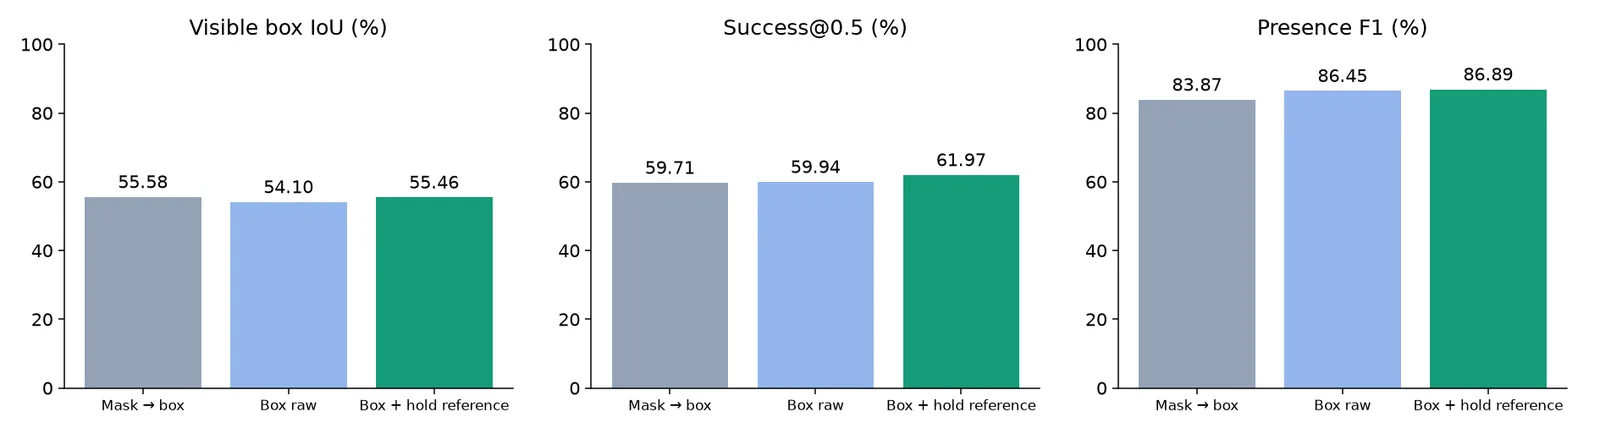
Full SA-V validation · 1008 pxVisible IoUSuccess@0.5Presence F1
Mask → box55.58%59.71%83.87%
Box raw54.10%59.94%86.45%
Box + hold reference55.46%61.97%86.89%
The selected policy is 0.12 percentage points below mask-to-box IoU, with higher success and presence F1.

Stage 1 demo · box memory versus mask memory

Stage 1 tracking videos · all 32 original comparisons

All 32 original comparison videos are restored here. These are early-checkpoint demonstrations, not videos of the final phase-30 + hold-reference checkpoint.

Box memory versus mask memory

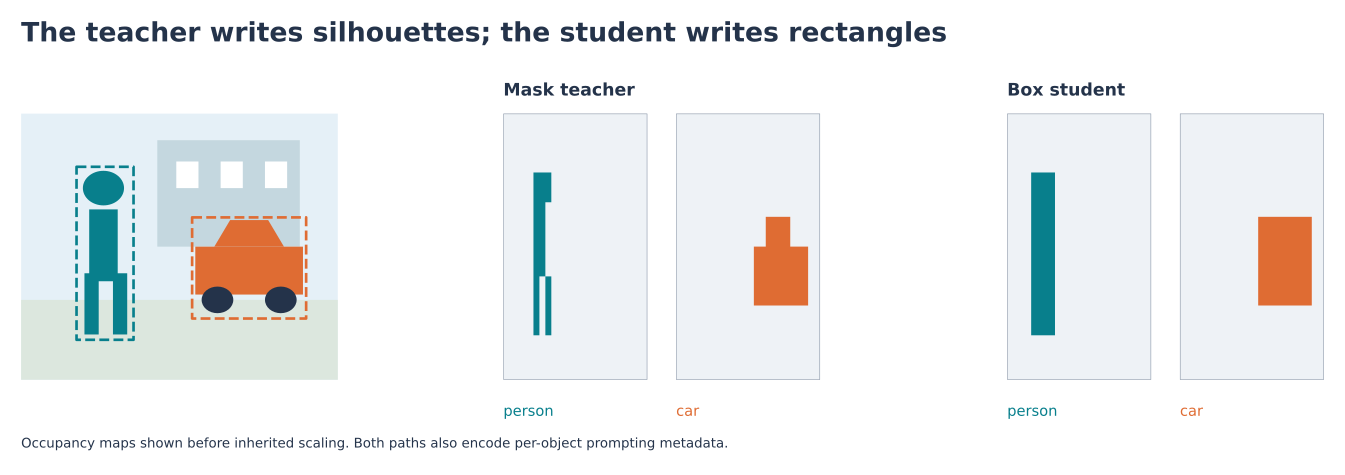
Silhouette and rectangle occupancy provide different spatial shapes for the same objects. Open full-size vector figure.
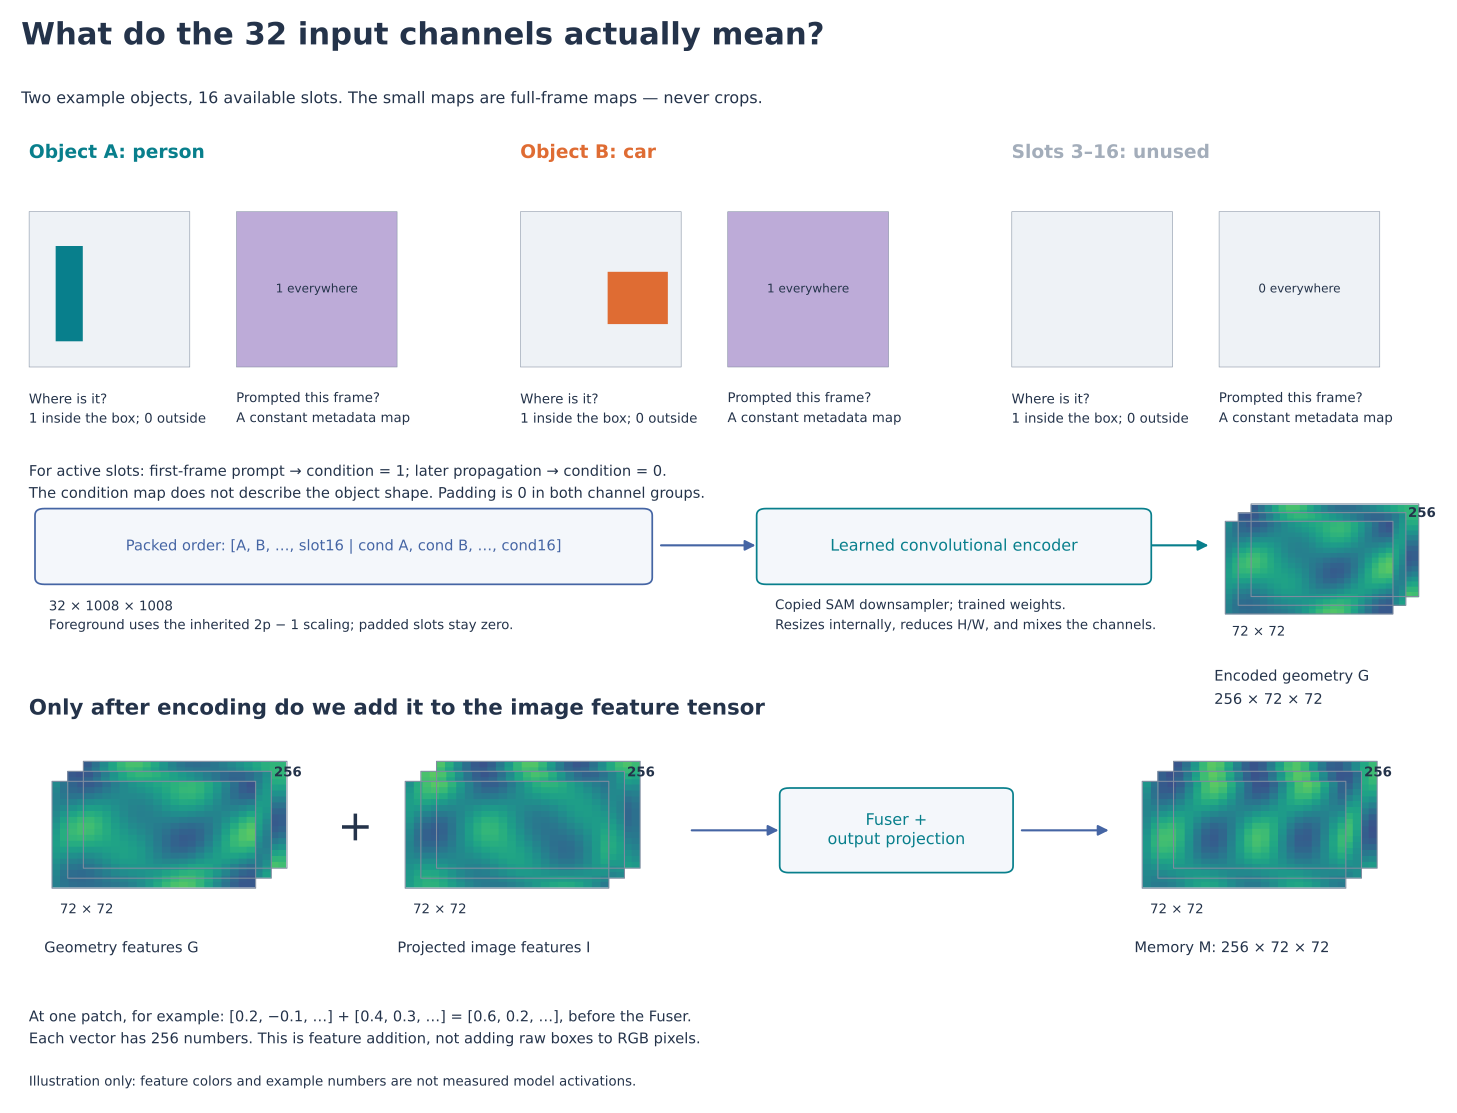
Prompt metadata is a constant map per object. A learned encoder maps 32 input channels to 256 feature channels before addition to image features. Open full-size vector figure.
ComponentMask teacherSelected box student
Object outputSegmentation maskDetector-reference 2D box and presence
Memory geometryMask probabilityDifferentiable rectangle occupancy, gated by presence
Encoder weightsOfficial SAM modulesInitialized from the teacher; trained downsampler, image projection, Fuser and output projection
FusionProjected image features + encoded geometrySame additive fusion, followed by Fuser
BackgroundSpatial feature map with object conditioningFull spatial feature grid remains; outside-box features are not forcibly zeroed
Multi-object stateMultiplex object slots and pointersSame mechanism; 16 slots per bucket, additional buckets for more objects

Training recipe

SettingSelected phase-30 run
DataSA-V manifest: 50,583 records; sampling/retries/padding do not imply one unique successful update per record
Batch and clip8 GPUs; one 8-frame clip per GPU; up to 16 sampled initial objects per clip; 1008 × 1008
Schedule3 data epochs split into 10 phases each; checkpoint phase 30. This is not 30 complete data epochs.
Learning rate2 × 10⁻⁶ base LR
ObjectivesGT box 5; teacher-box KD 5; GIoU 2; GT presence 1; presence KD 1; memory 1; pointer 0.1
Frozen / trainableFrozen RGB backbone and teacher; trainable student decoder, rectangle encoder, memory attention and pointers
The student learns both box outputs and recurrent memory behavior from the mask teacher, with matched object slots.

Final evaluation and provenance

Secondary ablation on the same 155 videosVisible IoUStatus
Initial-memory KD continuation54.00%Not selected
Long-clip 16-frame continuation54.02%Not selected
Updated 2026-09-17 · Consolidated from saved experiment artifacts and inspected implementation · Historical URLs remain available with archive notices.