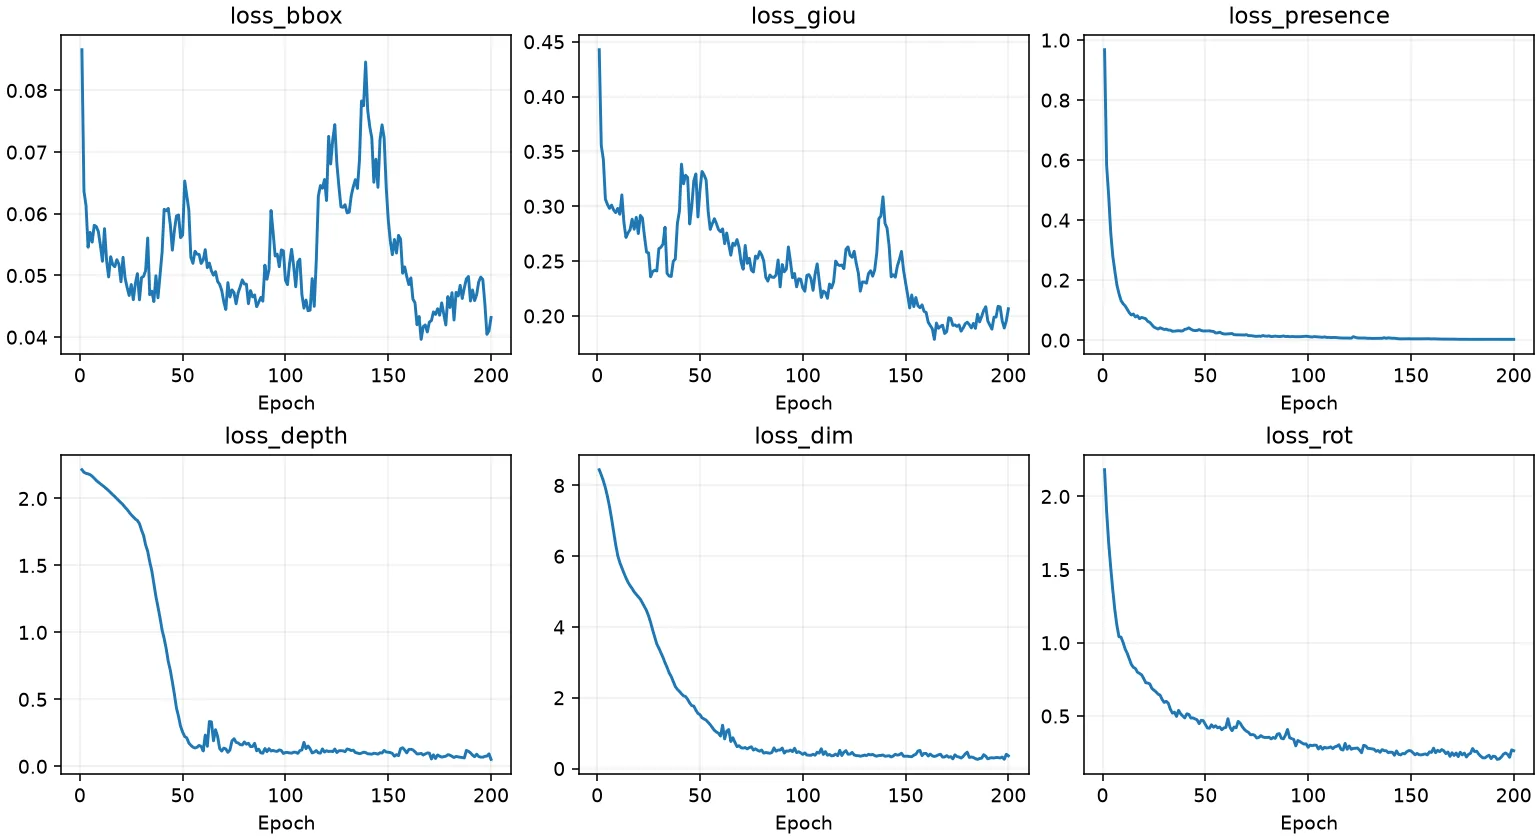
Four training videos · 200 epochs / 800 steps · seven held-out clips
200 epochsnot near-perfectearlier architecture
Current project overview
Latest conclusion
The four-video experiment did not achieve near-perfect overfit. This run uses the earlier model, before the native-head alignment refactor.
Run
Clip
Training
Initialization
Latest: 4 videos
8 frames, 2 FPS, 1008 px
200 epochs / 800 steps
Pretrained 2D student + newly initialized 3D head
Fixed windows span 3.5 seconds; batch size is one clip. This run starts from the pretrained 2D student and a newly initialized 3D head.
Frozen RGB backbone; temporal training phase. Depth dropout and photometric augmentation are off for this diagnostic.
Only the first frame supplies prompts. Later manual 2D and smoothed pseudo-3D labels are supervision, not inputs.
Seven held-out clips are excluded from this 3D run. This is not a claim they were unseen during upstream backbone or box-student training.
Training-set fit
Run
2D IoU ↑
Center error / m ↓
Size relative ↓
Rotation ↓
3D joint pass ↑
4 videos
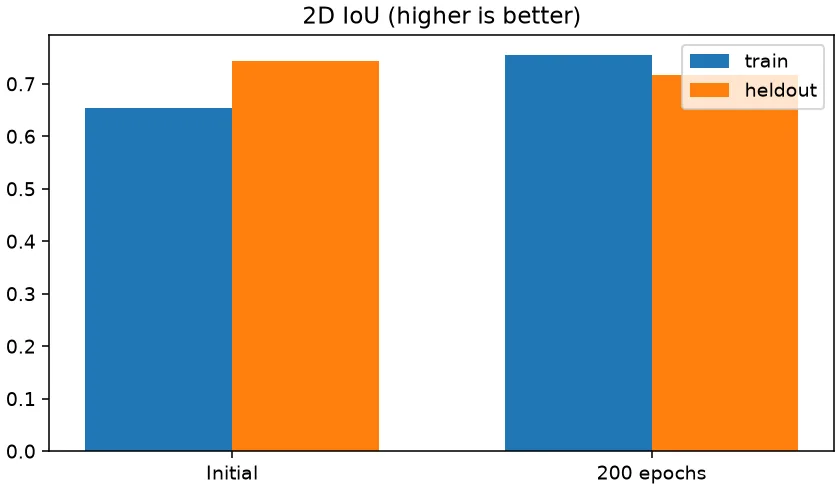
0.755
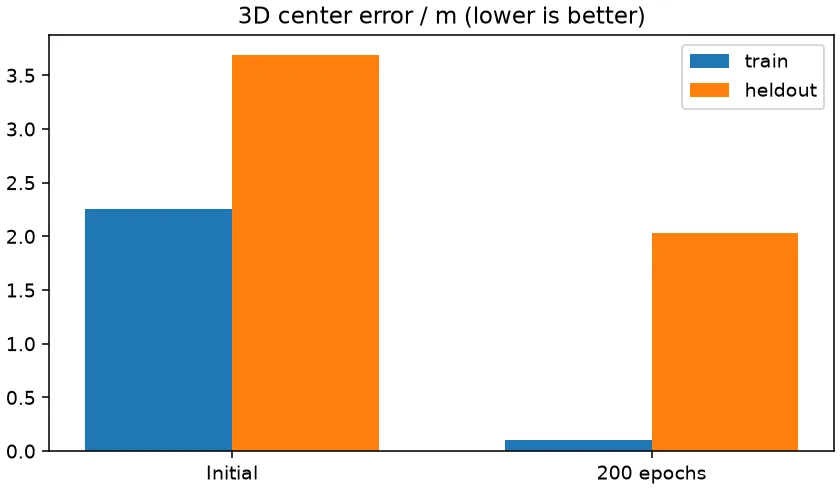
0.107
6.1%
7.1°
24.4%
Means are over eligible object-frames, not equal-weight video means. These are errors against pseudo labels, not sensor ground truth.
3D joint pass requires center relative error ≤5%, mean dimension relative error ≤5%, and rotation error ≤5° simultaneously.
Near-perfect diagnostic requires ≥95% of eligible 2D frames at IoU ≥0.95 and ≥95% 3D joint pass. This run does not pass.
Four-video run: saved training/evaluation diagnostic; earlier model implementation.Four-video run: saved training/evaluation diagnostic; earlier model implementation.Four-video run: saved training/evaluation diagnostic; earlier model implementation.
Latest four-video training visualizations
All four training videos are shown; these are fixed short clips, not long-video evaluation.
sav_008220
sav_006689
sav_010240
sav_002191
Held-out results
Run
2D IoU ↑
Center error / m ↓
Size relative ↓
Rotation ↓
3D joint pass ↑
4 videos
0.716
2.030
84.1%
30.4°
0.0%
Held-out 3D errors remain much larger; training-set improvement does not establish generalization.
The seven videos below belong to the four-video experiment.
sav_007427
sav_012325
sav_005179
sav_003740
sav_004680
sav_007694
sav_002079
Data and depth debugging
The input inspector shows original RGB, training boxes, pseudo-3D projections, exact FP32 patch depth and valid coverage for the same four clips.
The depth range control changes visualization only; hover values remain metric input observations.
Open the RGB / depth inspector
Remaining questions
The temporal audit found no large equivalent-orientation representation jump in these four short clips. That finding does not rule out other pseudo-label noise or implementation/optimization issues.
The current native-head and auxiliary-supervision refactor has passed implementation tests but has not yet been retrained in this experiment.
The cause of incomplete fitting is unresolved; no successful rerun is claimed here.
Updated 2026-09-17 · Consolidated from saved experiment artifacts and inspected implementation · Historical URLs remain available with archive notices.