| Component | Current contract |
|---|
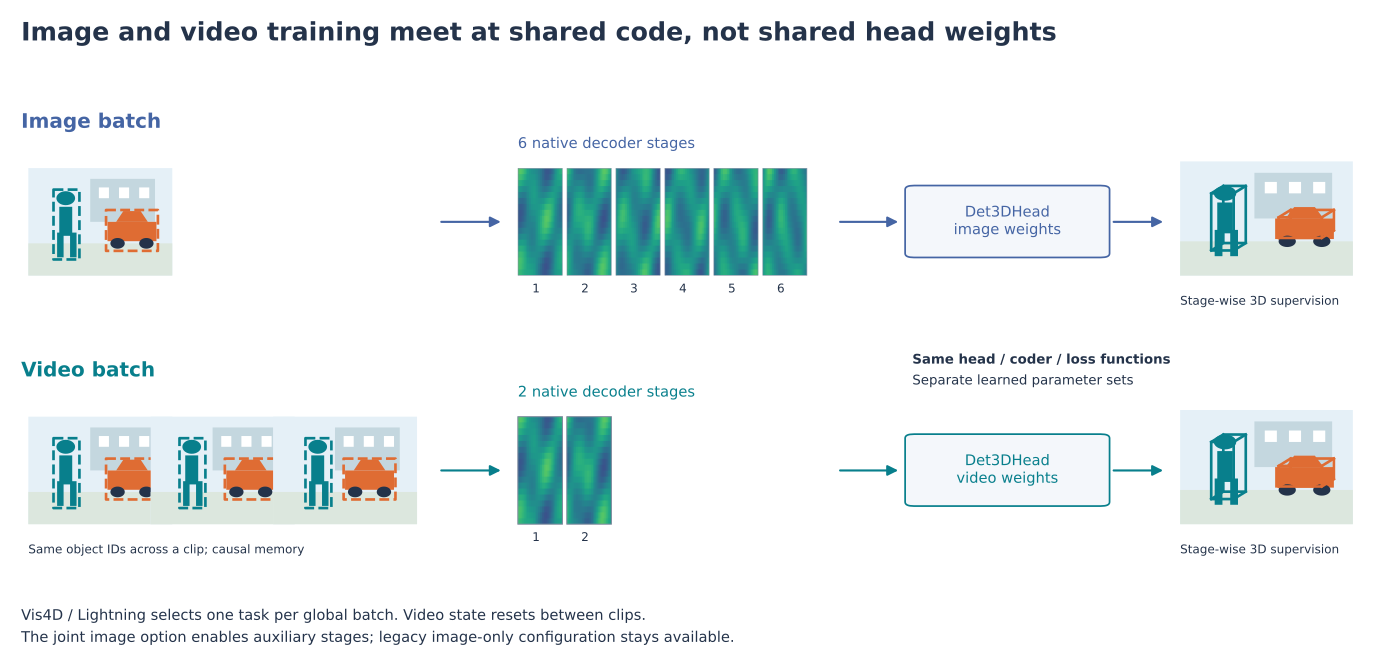
| 3D head | Same Det3DHead class and predict_box3d_stages function; separate image/video weights |
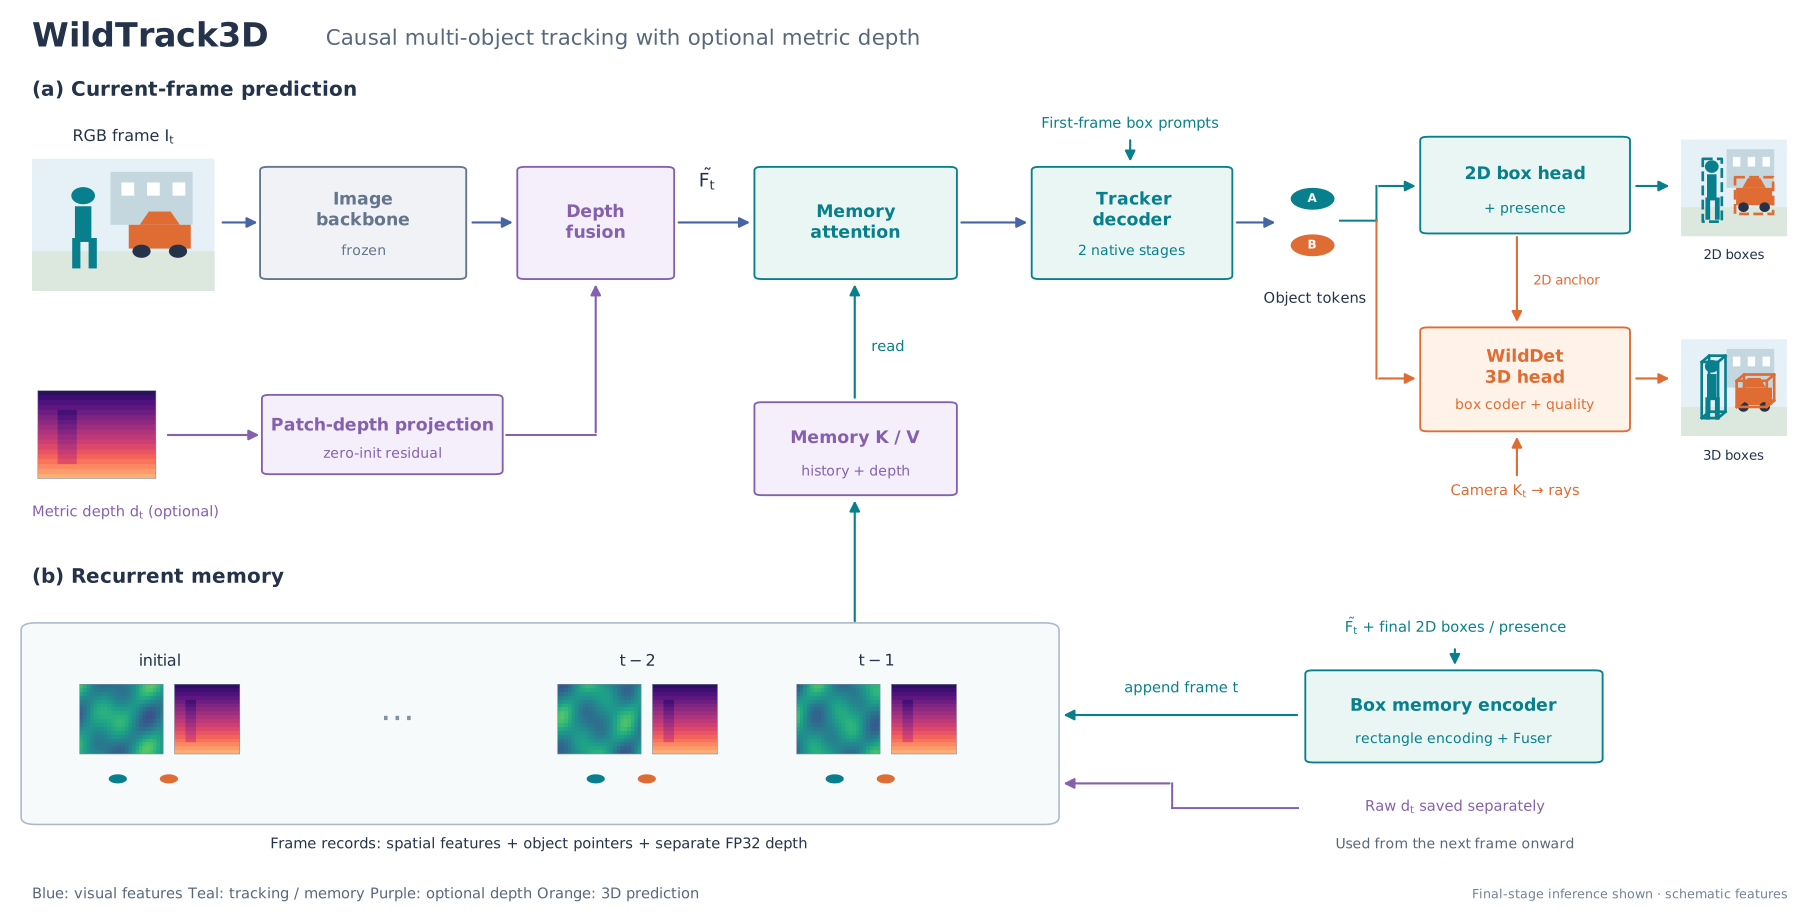
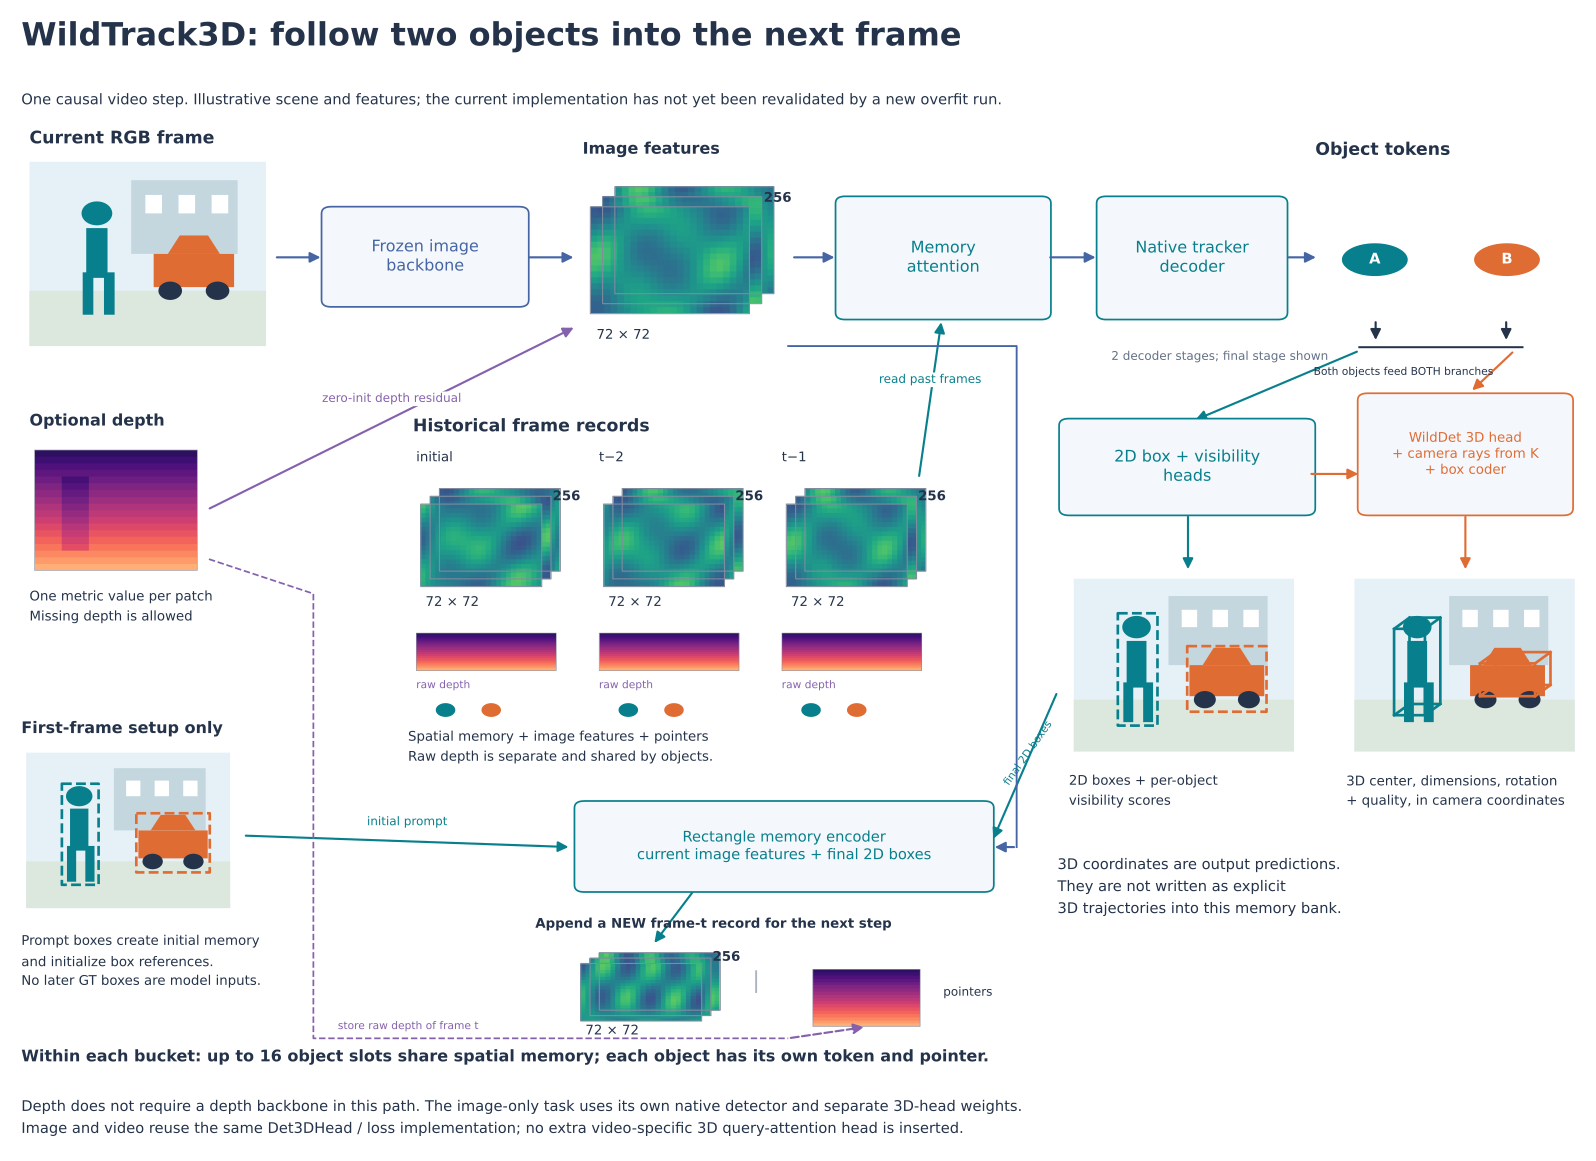
| Video queries | Native selected decoder object tokens before pointer projection; removed the earlier extra query embedding/patch-attention path |
| Auxiliary supervision | Video: 2 native stages / 1 auxiliary. New joint image config: 6 stages / 5 auxiliary; legacy image default preserved |
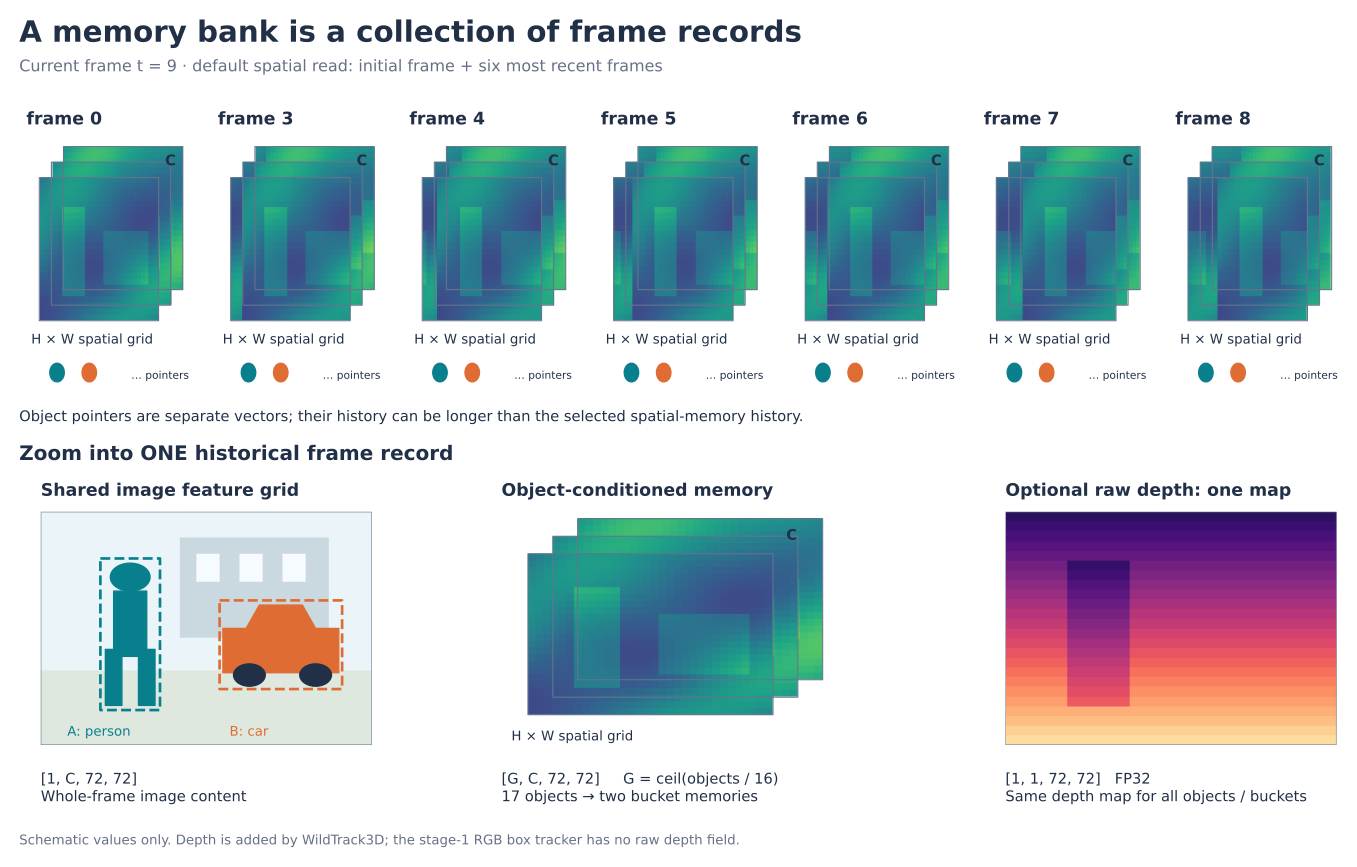
| Memory | SAM causal multiplex tracking; bucket padding is never a target; only final stage writes memory |
| Detection-specific logic | Matching, O2M and text classification remain on the image path |
| Scope | First-frame prompted objects; no automatic object births or global re-identification |