how v12 was trained, and where it stands vs TRELLIS.2 / TRELLIS-text / TIGON · 2026-09-15
trainingbenchmarkimage-to-3Dtext-to-3Dv12
TL;DR
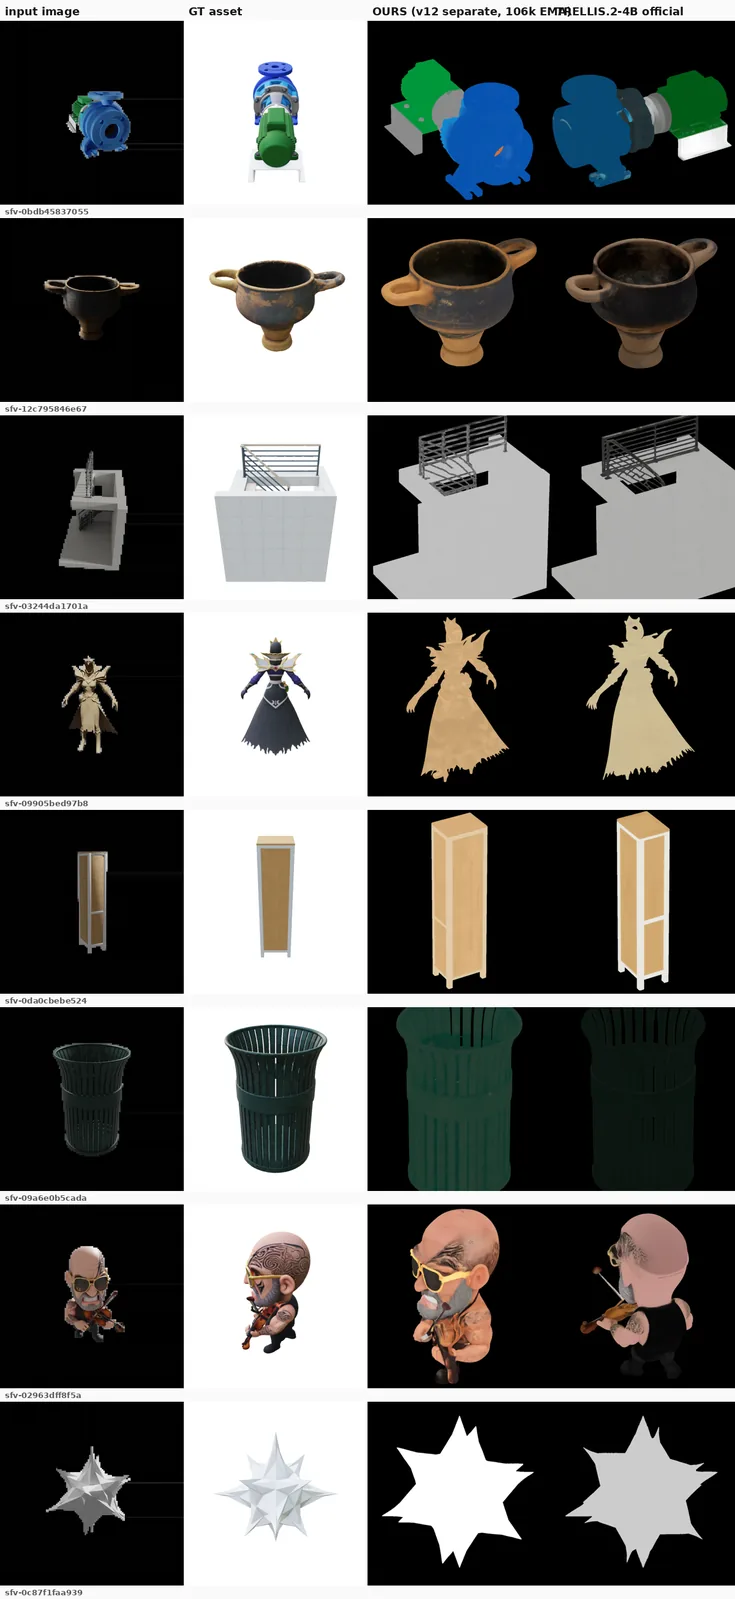
Image-to-3D: on par with TRELLIS.2-4B end-to-end and on geometry; materials clearly better (LPIPS −18%, PSNR +5 dB, wins 64–74% of cases).
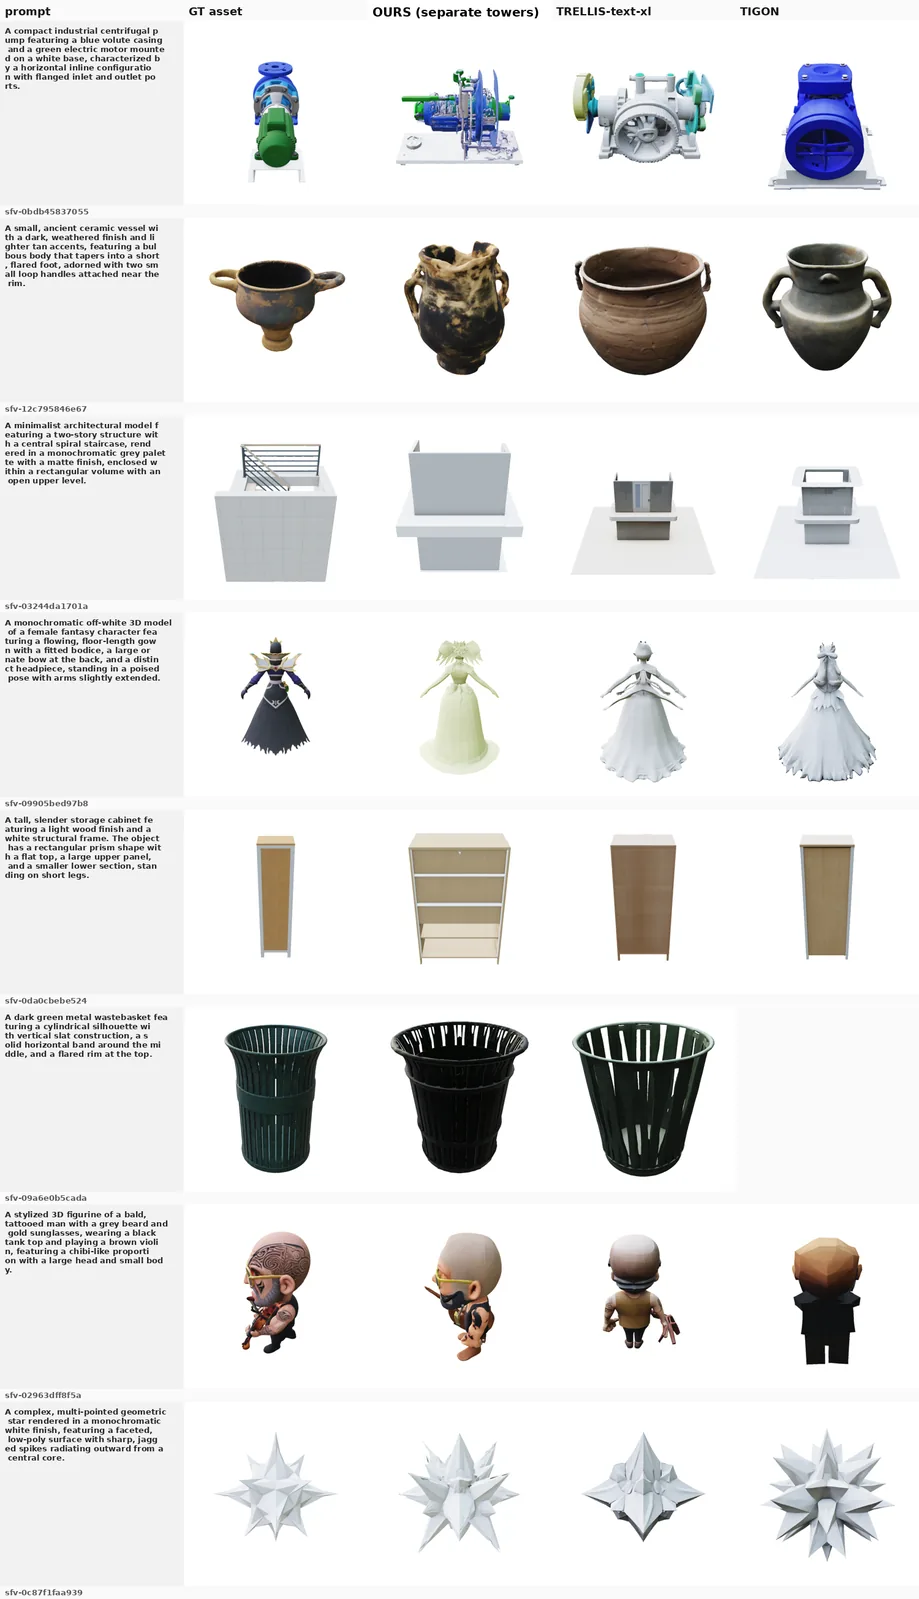
Text-to-3D: ~0.9 CLIP-T behind TRELLIS-text / TIGON. Cause: the SS tower barely reads text (sensitivity 1.28 vs 2.1 for images). Not a sampler issue, not a pipeline issue.
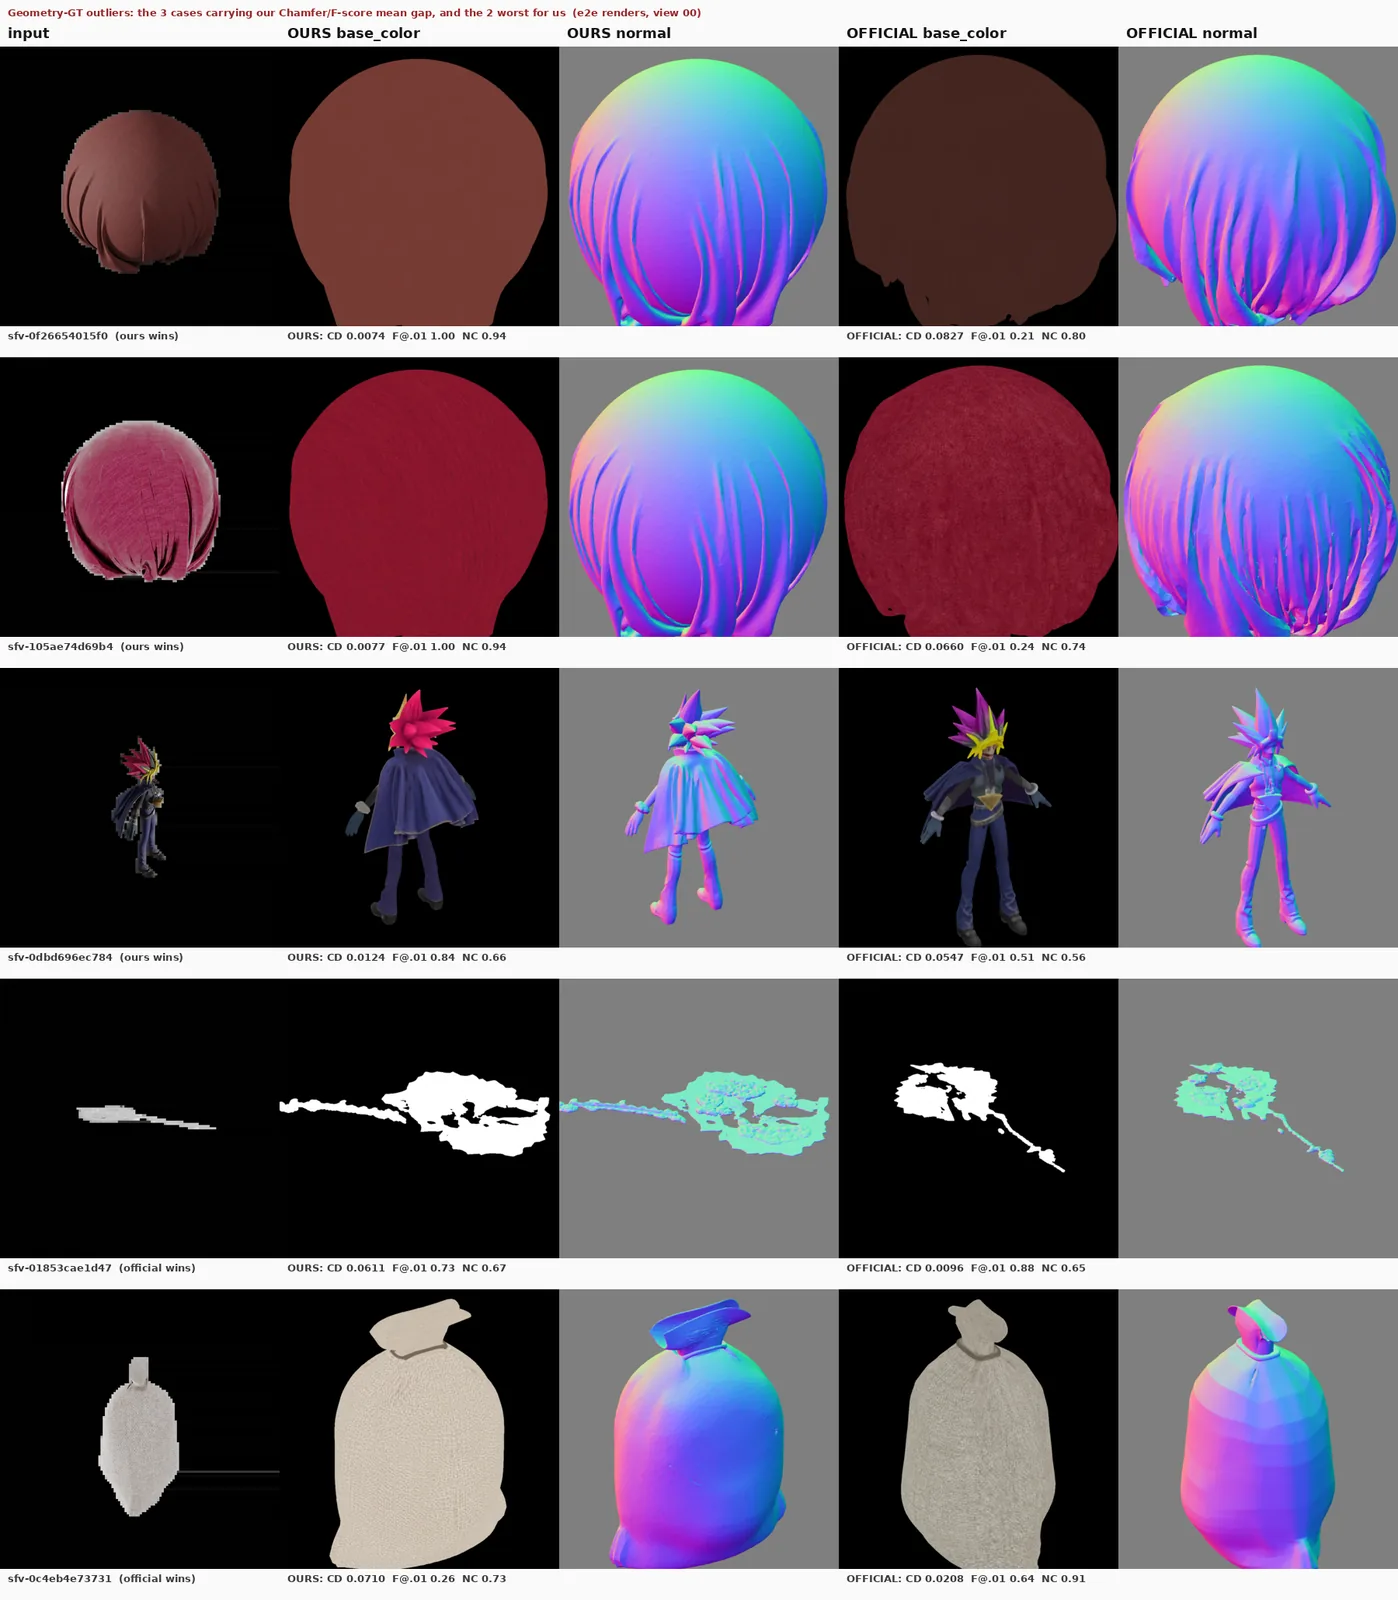
8 of the 50 eval meshes exist verbatim in the training pool under other ids (one mesh 2,163×). Geometry numbers exclude them; eval split needs a geometry-hash rebuild.
1 · Stages
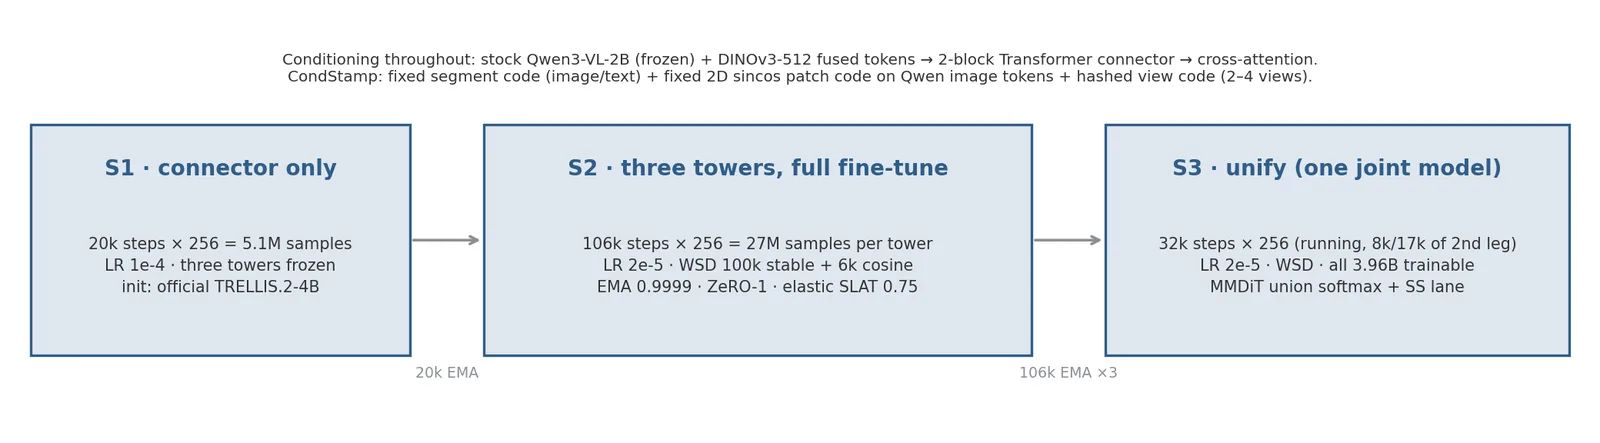
S1 = train the connector only. S2 = unfreeze the three towers. S3 = merge the three towers into one joint model (running).
Condition: stock Qwen3-VL-2B (frozen) + DINOv3, fused tokens → cross-attention. Same in every stage.
S1 20k → S2 106k per tower → S3 32k. Effective batch 256 everywhere; WSD schedule; EMA 0.9999.
2 · Data
1.47M real assets (TexVerse, Sketchfab, ObjaverseXL, HSSD, ABO, Toys4k, SWH) + 0.48M synthetic (text→image→3D). Eval assets removed by sha.
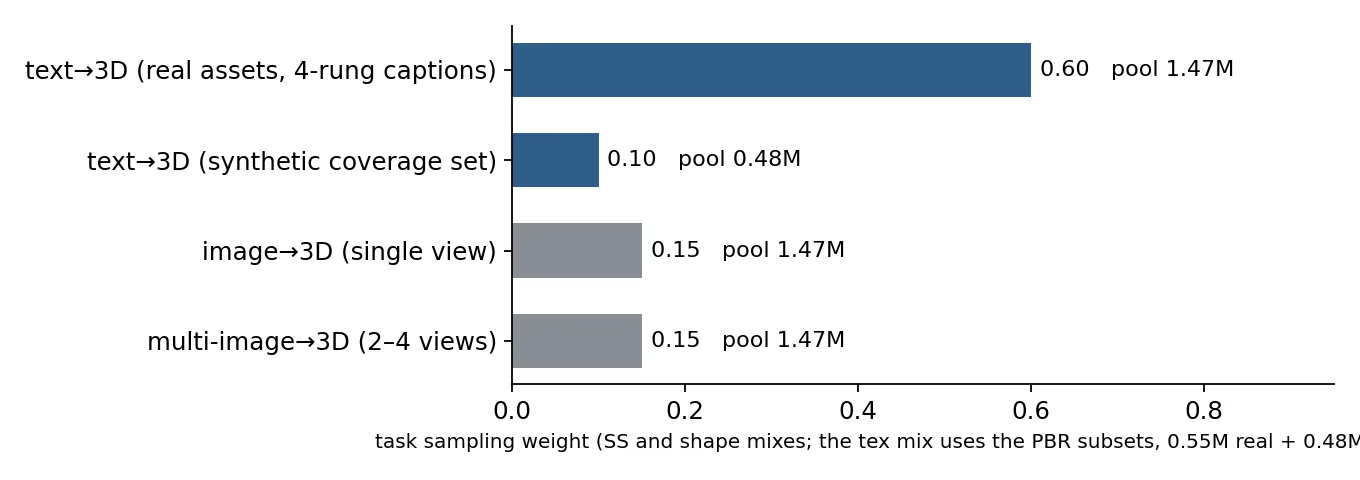
27M samples per tower in S2 (106k steps × 256). Text tasks get 70% of batches.
Per-batch task mix. The tex tower uses only assets that have PBR latents (0.55M + 0.48M).
3 · ROAD
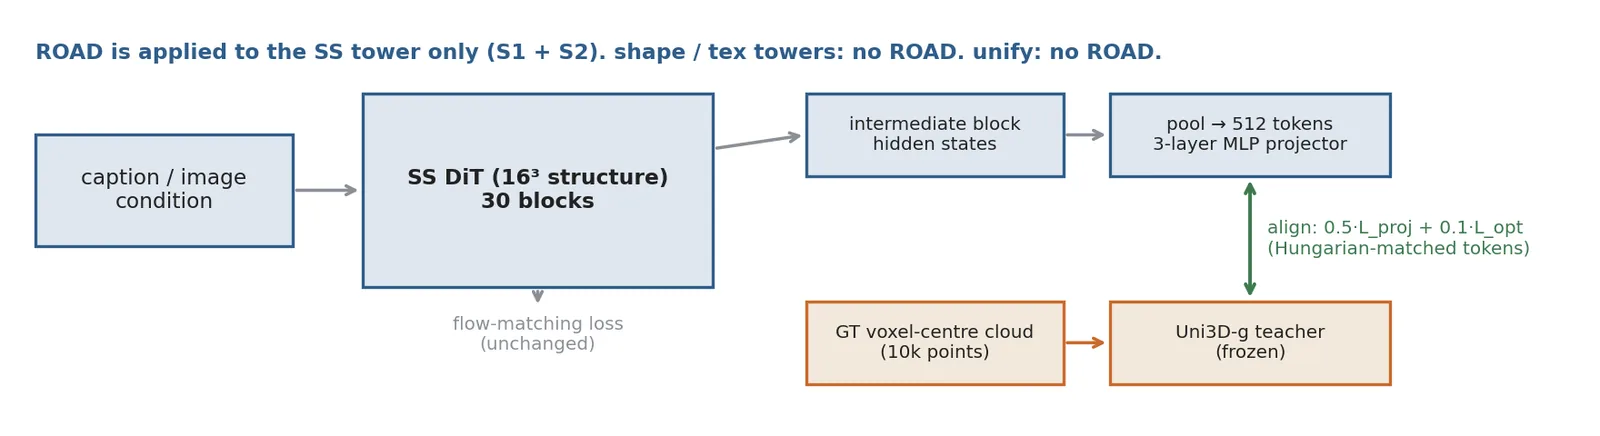
Only on the SS tower. Aligns SS hidden tokens to a frozen Uni3D-g teacher on the GT point cloud (ROAD, arXiv 2607.28581, vendored verbatim).
Loss = flow matching + 0.5·L_proj + 0.1·L_opt. shape / tex / unify: no ROAD.
4 · CFG sweeps (per tower, text path, 8 pinned assets, picked by eye)
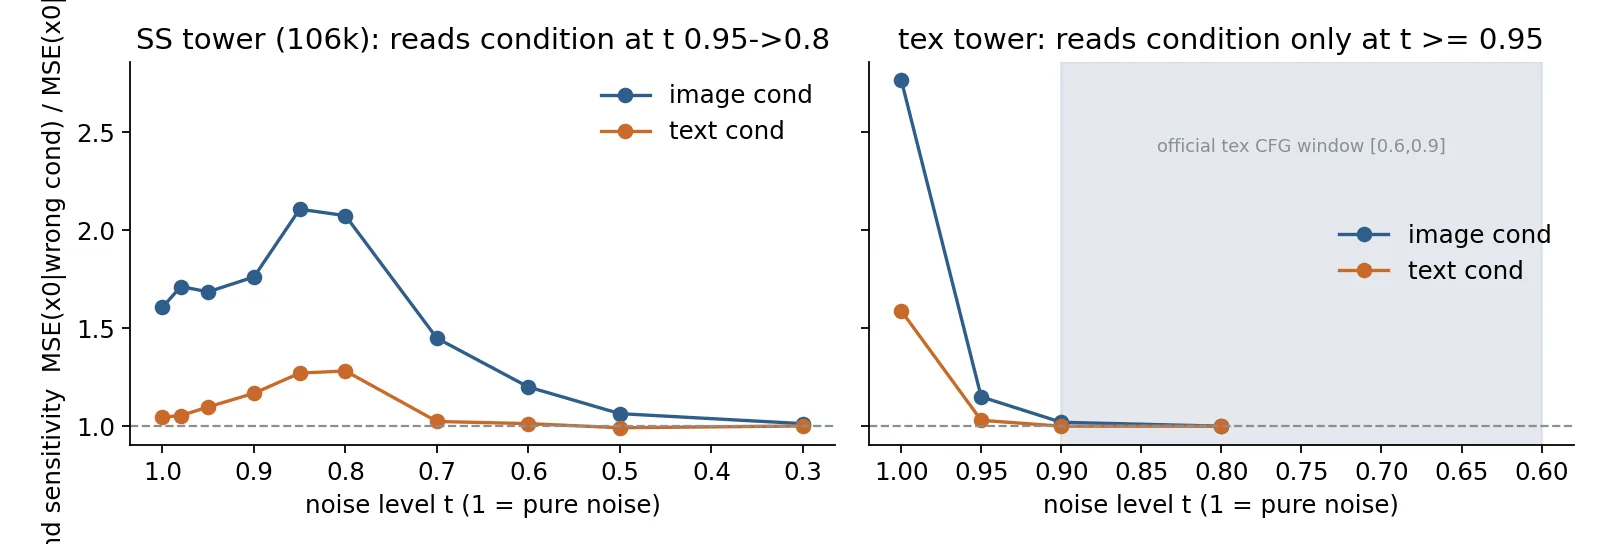
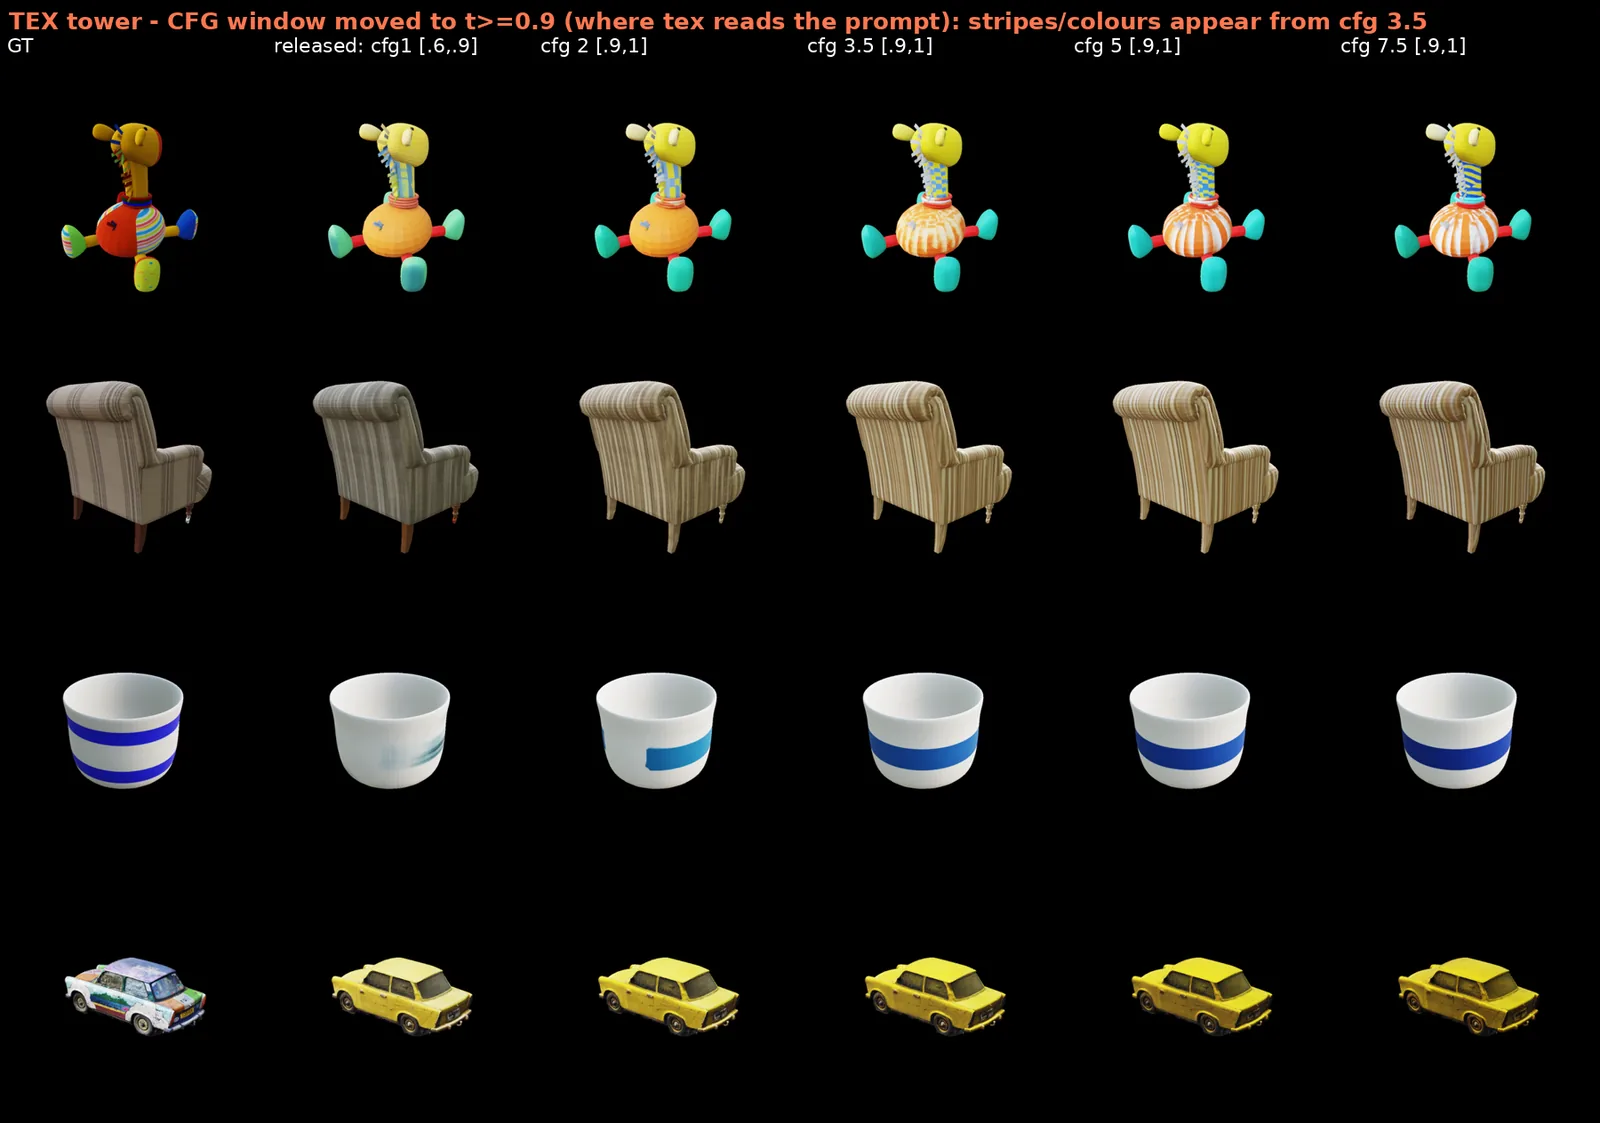
Probe first (fig. a): a wrong-vs-right condition test shows when each tower reads its condition. tex only at t ≥ 0.95 → the official tex window [0.6, 0.9] never applies text CFG.
Then sweep each tower alone with the other two fixed (figs. b–d).
tower
image path
text path
SS
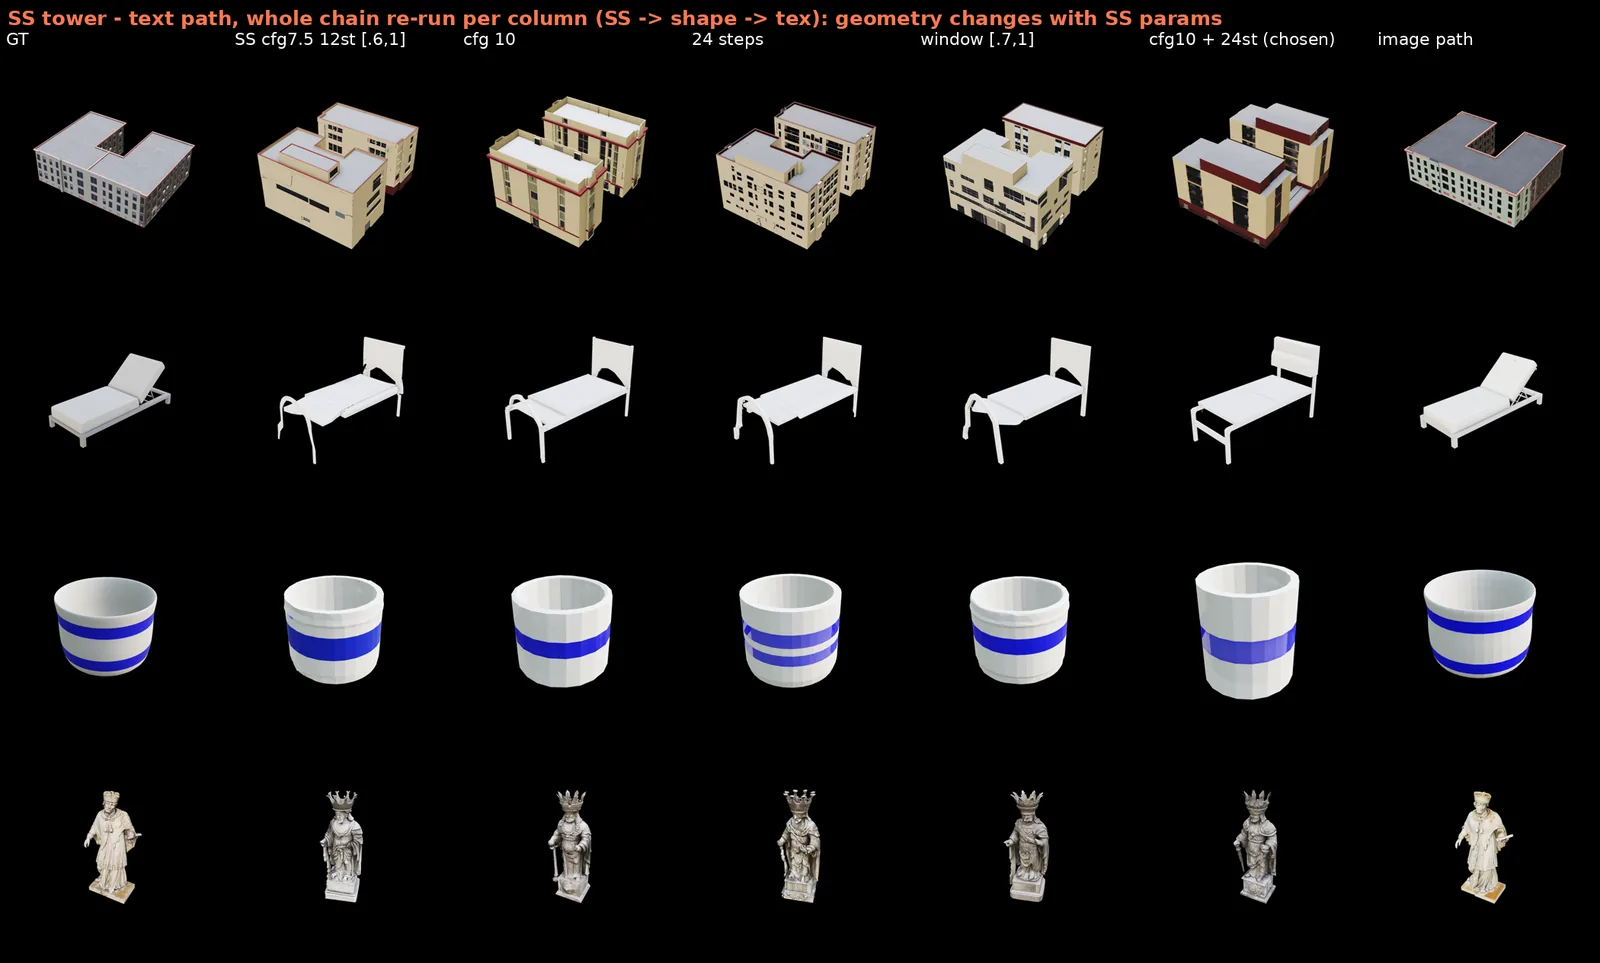
24 steps · cfg 10 · rescale 0.7 · [0.6, 1] · rt 5
same
shape
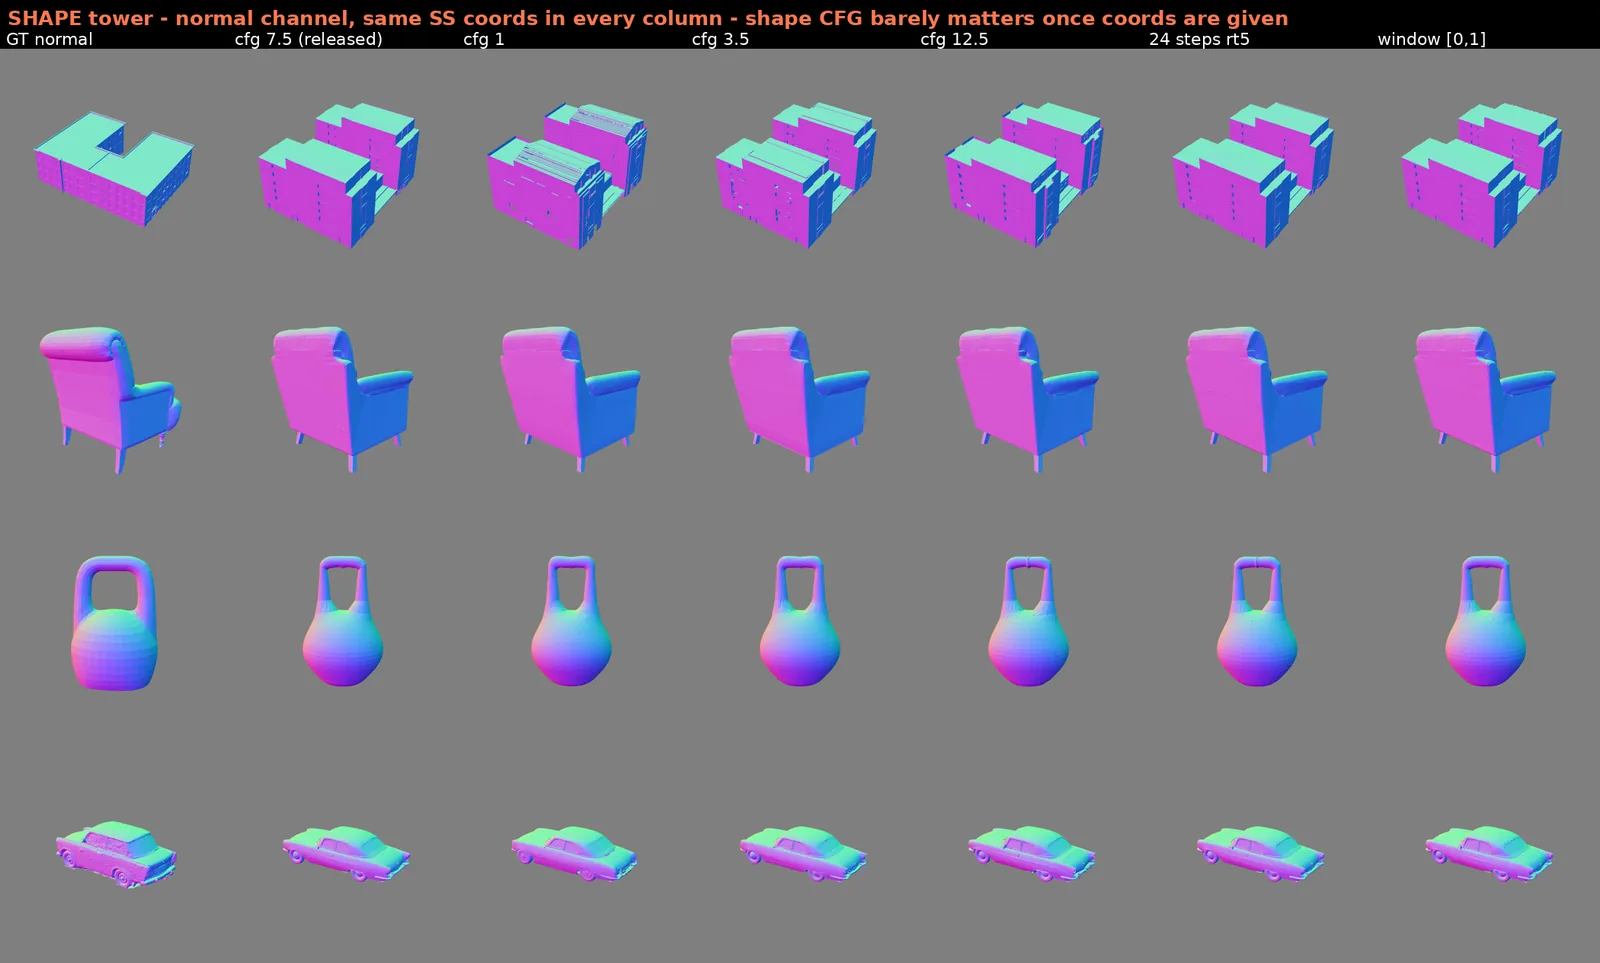
official: 12 · 7.5 · 0.5 · [0.6, 1] · rt 3
same
tex
official: 12 · cfg 1.0 (off) · [0.6, 0.9] · rt 3
24 · 7.5 · 0.5 · [0.9, 1] · rt 5
(a) Condition-sensitivity probe. SS reads at t 0.95→0.8 (text ~4× weaker than image); tex reads only at t ≥ 0.95, outside the official window (shaded).(b) tex tower, GT geometry locked. Released setting (cfg 1, [0.6,0.9]) loses the prompt's stripes/colours; window [0.9,1] + cfg ≥ 3.5 brings them back; cfg 7.5 rs 0.5 chosen.(c) SS tower, whole chain re-run per column. cfg and step count change the structure itself (building, bed, mug); cfg 10 + 24 steps chosen. Text path stays worse than the image path on the same asset.(d) shape tower, same SS coords in every column, normal channel. cfg 1 → 12.5 and window changes barely move the surface → kept the official setting.
5 · WilD3D benchmark scores
Held-out Sketchfab assets, same image / prompt / camera / seed for every model. TRELLIS.2-4B at the 512 pipeline. Image path n=42 (8 cases whose exact mesh exists in the training pool removed). Bold = better; * = paired t-test p < 0.05.
Image-to-3D
scorecard
metric
TRELLIS.2-4B
ours (separate towers)
E2E
CLIP ↑
0.867
0.866
E2E
ULIP-I ↑
0.454
0.454
E2E
Uni3D-I ↑
0.395
0.389
Geometry-GT
Chamfer ↓
0.0409
0.0393
Geometry-GT
F@0.01 ↑
0.547
0.568
Geometry-GT
F@0.02 ↑
0.727
0.746
Geometry-GT
Normal cons. ↑
0.675
0.694*
Texture-GT (on GT geometry)
LPIPS ↓
0.189
0.155*
Texture-GT (on GT geometry)
PSNR ↑
17.3
22.4*
Texture-GT (on GT geometry)
SSIM ↑
0.606
0.664*
Texture-GT (on GT geometry)
CLIP-I ↑
0.951
0.962*
Texture-GT set-level
FID ↓
123
100
Texture-GT set-level
CMMD ↓
0.045
0.024
Text-to-3D
model (n=50, same prompts)
CLIP-T ×100 ↑
ULIP-T ↑
Uni3D-T ↑
Hungarian-CLIP ↑
KD-DINOv2 ×100 ↓
FD-point ↓
GT asset (ceiling)
26.45
0.168
0.271
—
—
—
TRELLIS-text-xl
27.85
0.183
0.292
84.8
29.1
45.9
TIGON
27.74
0.185
0.287
84.5
24.8
43.8
ours (separate towers)
26.98
0.166
0.283
86.0
16.5
38.6
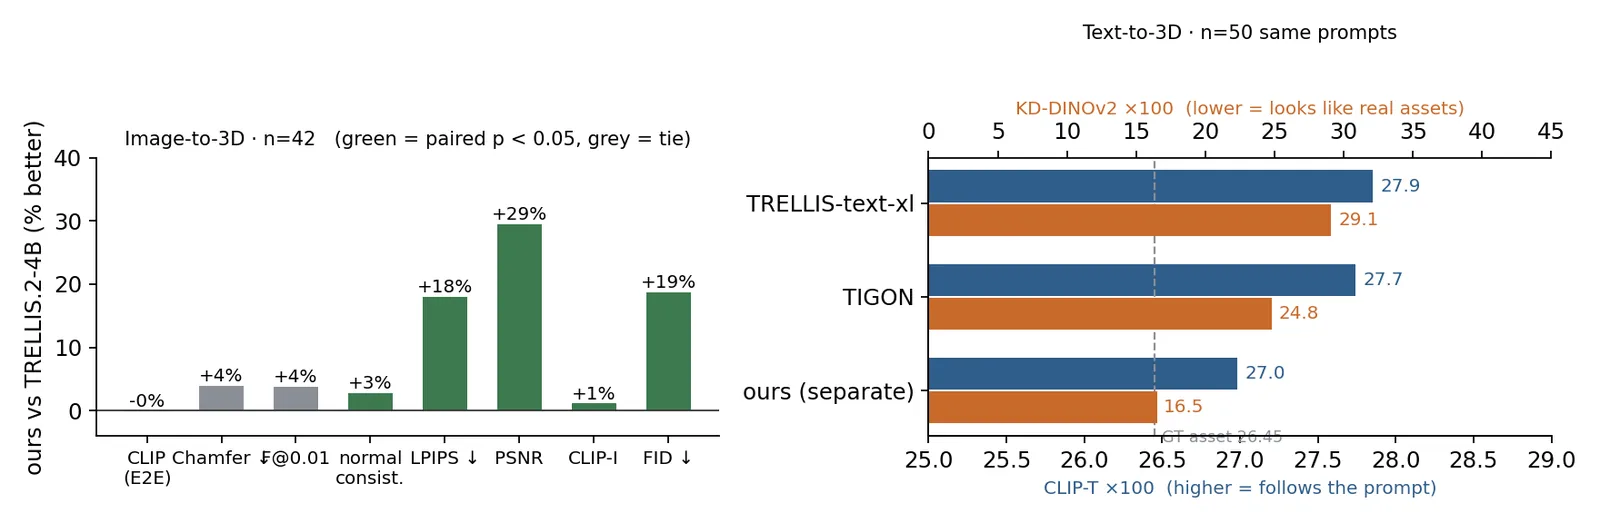
Image: E2E and geometry tie, normals smoother, materials clearly better. Text: baselines follow the prompt better (~0.9 CLIP-T); ours looks more like real assets. Bottleneck is SS text conditioning.
Caveats: single seed; official 512 only; Texture-GT is measured on this dataset's own GT materials.
Left: ours vs TRELLIS.2-4B per metric (% better, n=42). Right: text-to-3D, prompt alignment (blue) vs resemblance to real assets (orange).Image-to-3D examples: input | GT | ours | TRELLIS.2-4B.Text-to-3D examples, same assets: prompt | GT | ours | TRELLIS-text | TIGON. Pump, vessel, building: our structure falls apart; the rest are on par.The duplicate-mesh trap: rows 1–2 are one recoloured mesh present 2,163× in training — memorised (F@0.01 = 1.00), not generated. Excluded from the numbers.
6 · Next
Rebuild the eval split with geometry-hash dedup; dedup the training pool (14.9% duplicates in SketchfabV1).
Fix SS text conditioning (text-focused SS training / dedicated text SS / text→image→3D) — decision pending.
Finish unify (≈30 h), calibrate its CFG, rerun this benchmark.
v12 S2 finals = shape / tex / SS 106k EMA · results: eval_suite results sfv50_sep106k, text_sfv50_v12