3D-gen · v12 training data (evalclean pools, task mixture, per-task samples)
data snapshot 2026-09-03 · pools with every evaluation asset removed · three-tower v12 mixture 70 / 15 / 15
datav12mixturecontamination
TL;DR
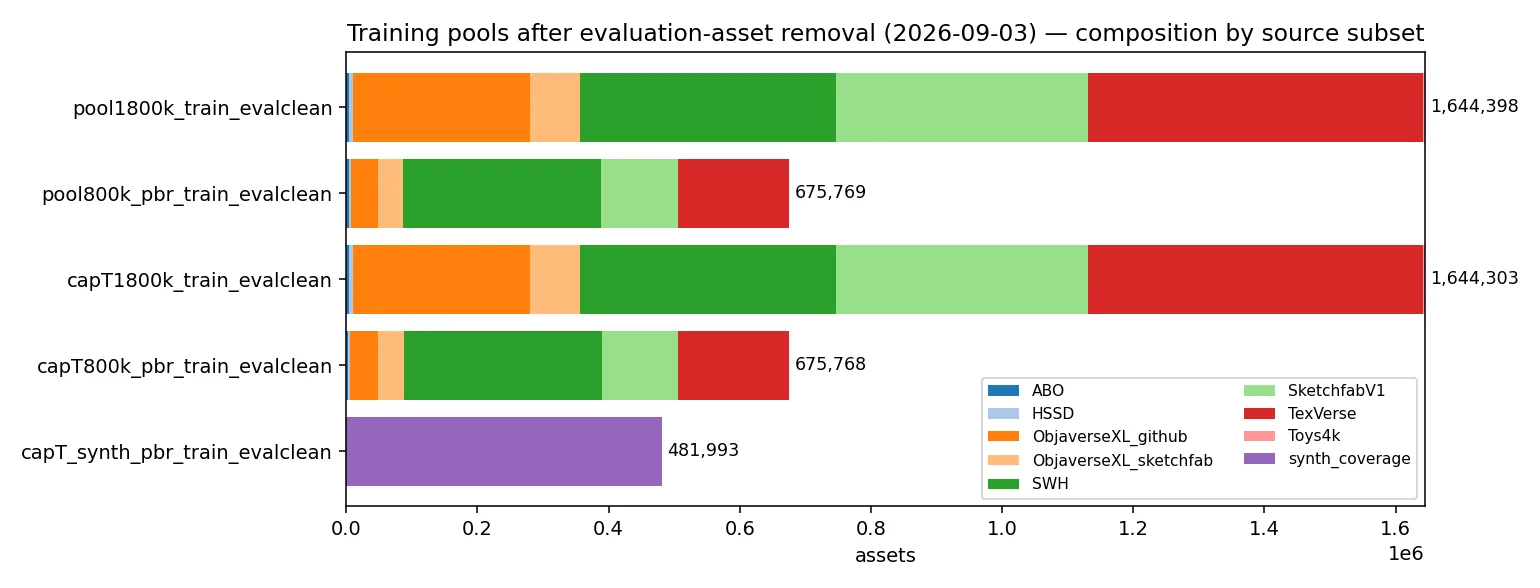
Every evaluation asset is now out of the training pools: 22 eval / held-out manifests (23,456 unique sha; SWH20/50/60, text eval47/50/pool60, Toys4K pilot20, all val/test/viz16/sketchfab held-outs, the old v5 1% held-out) were JSON-joined against every train manifest → splits/*_train_evalclean.jsonl, residual overlap 0. Models trained only on these (v12 S1 onward) are clean on the WilD3D SWH tracks; roadv1 / roadfrz / v10 stay contaminated.
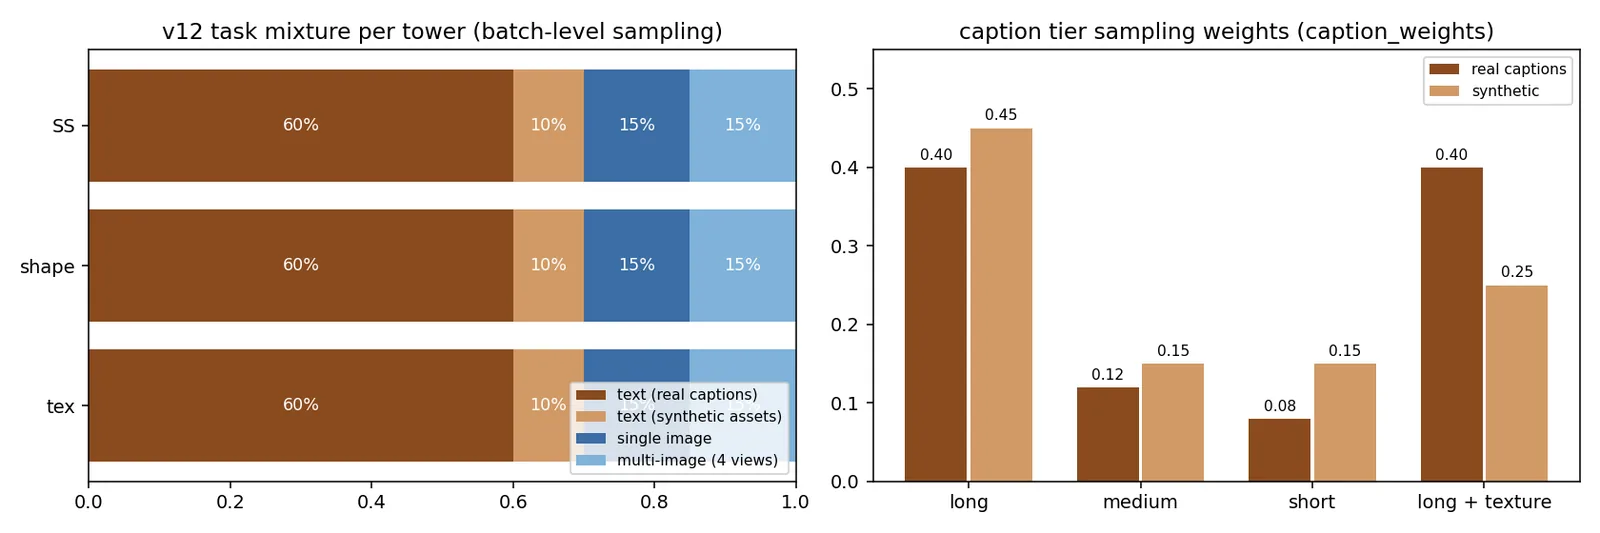
v12 mixture, identical for the three towers: text 70% (real captions 60% + synthetic assets 10%) · single image 15% · multi-image 15% (4 weighted views). Caption tiers are sampled with new caption_weights: real 0.40 / 0.12 / 0.08 / 0.40 (long-ish 80%), synthetic 0.45 / 0.15 / 0.15 / 0.25 (long-ish 70%).
Open item: real : synthetic is 6 : 1 in the committed yamls; roadv1 used 3 : 1 (0.6 / 0.2). Proposal on the table: 0.525 / 0.175 with images unchanged.
0 · What a training batch looks like
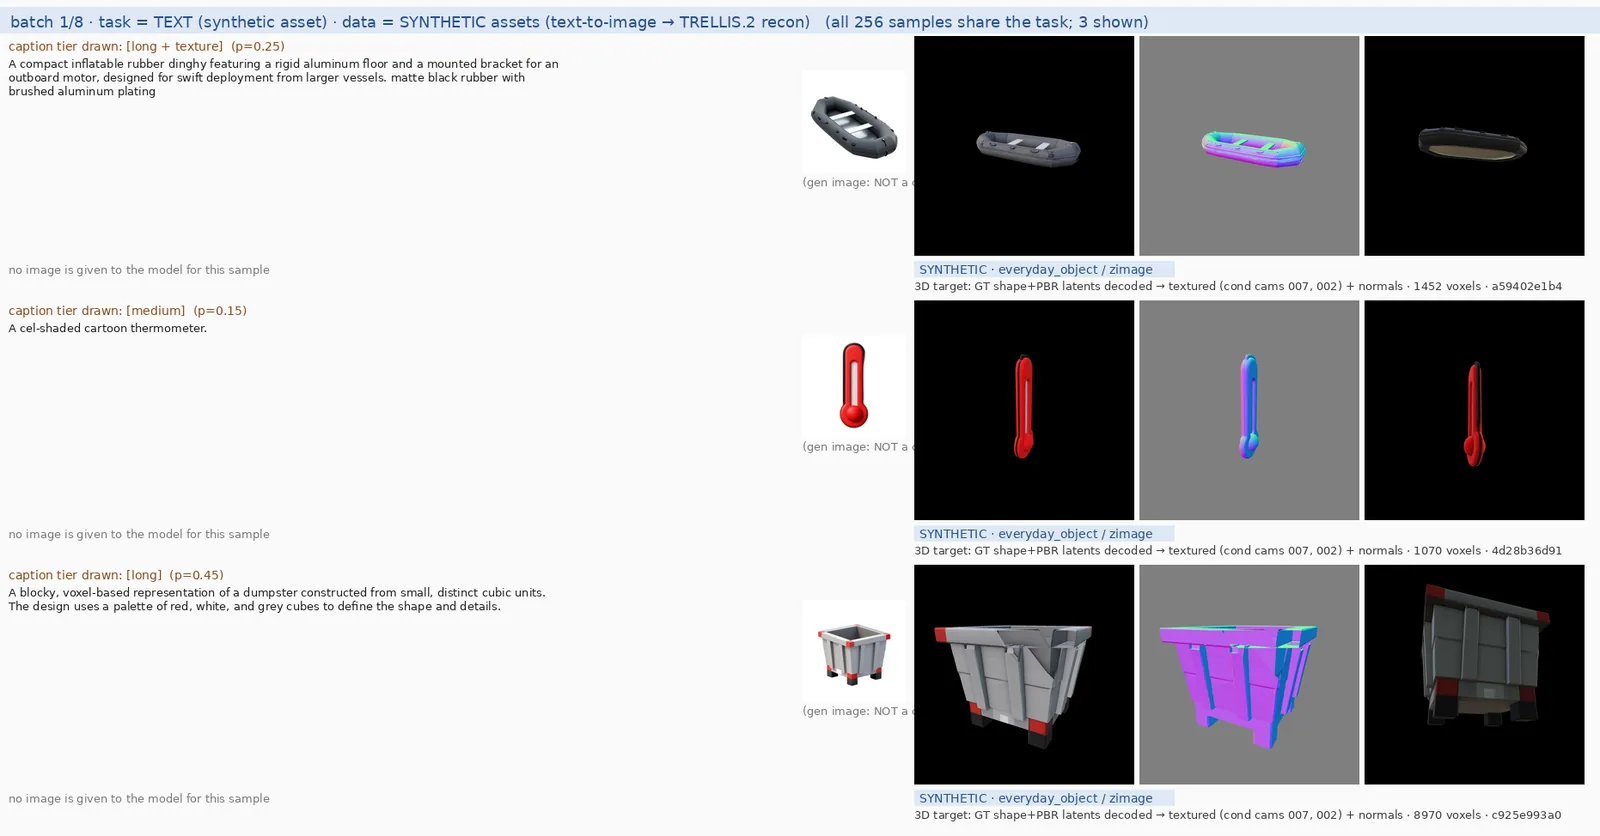
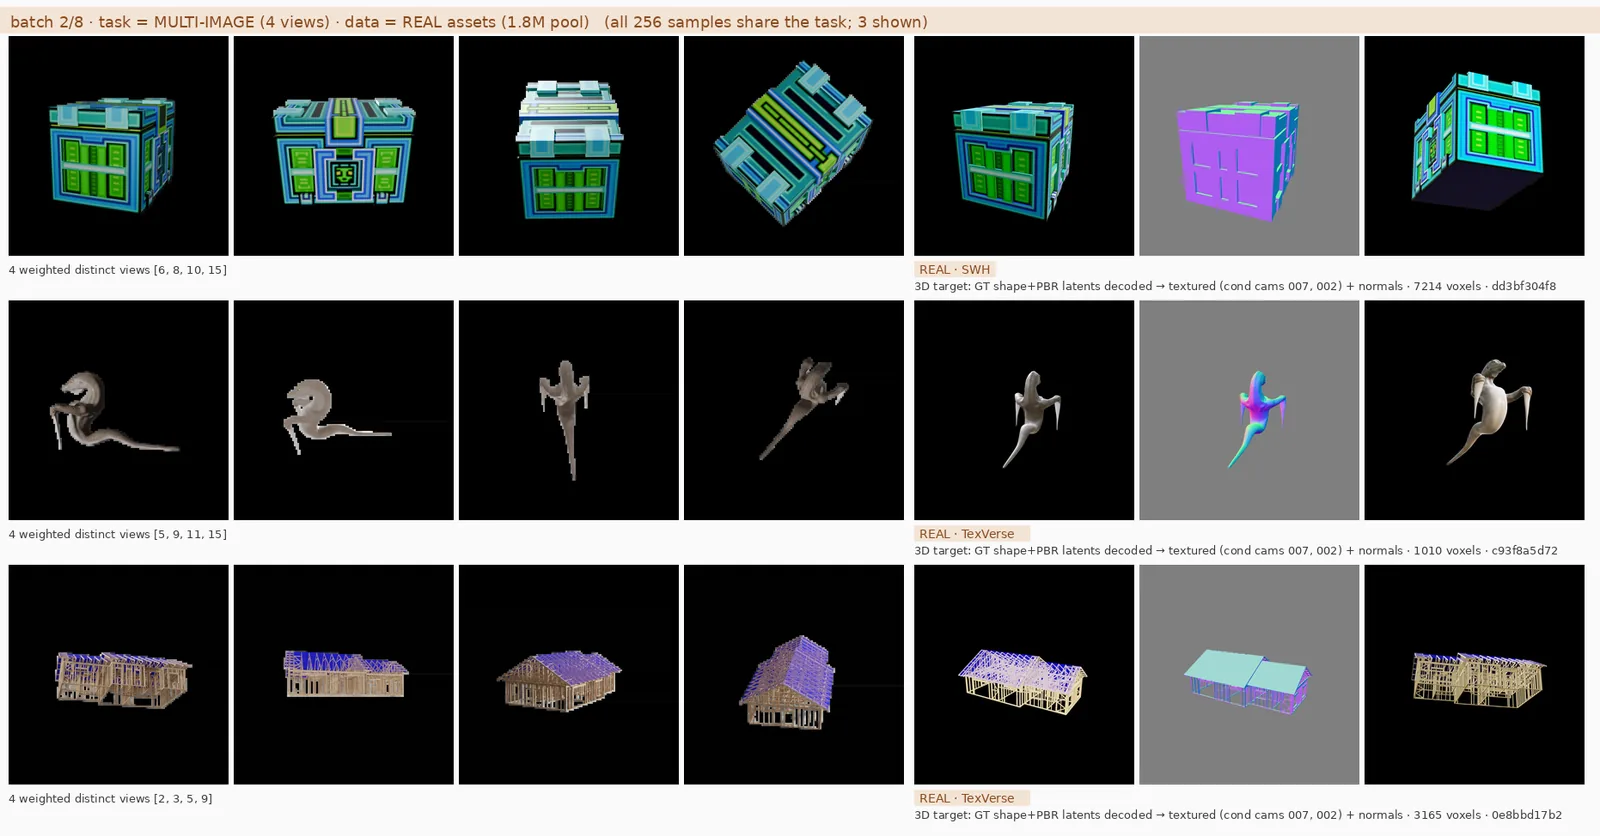
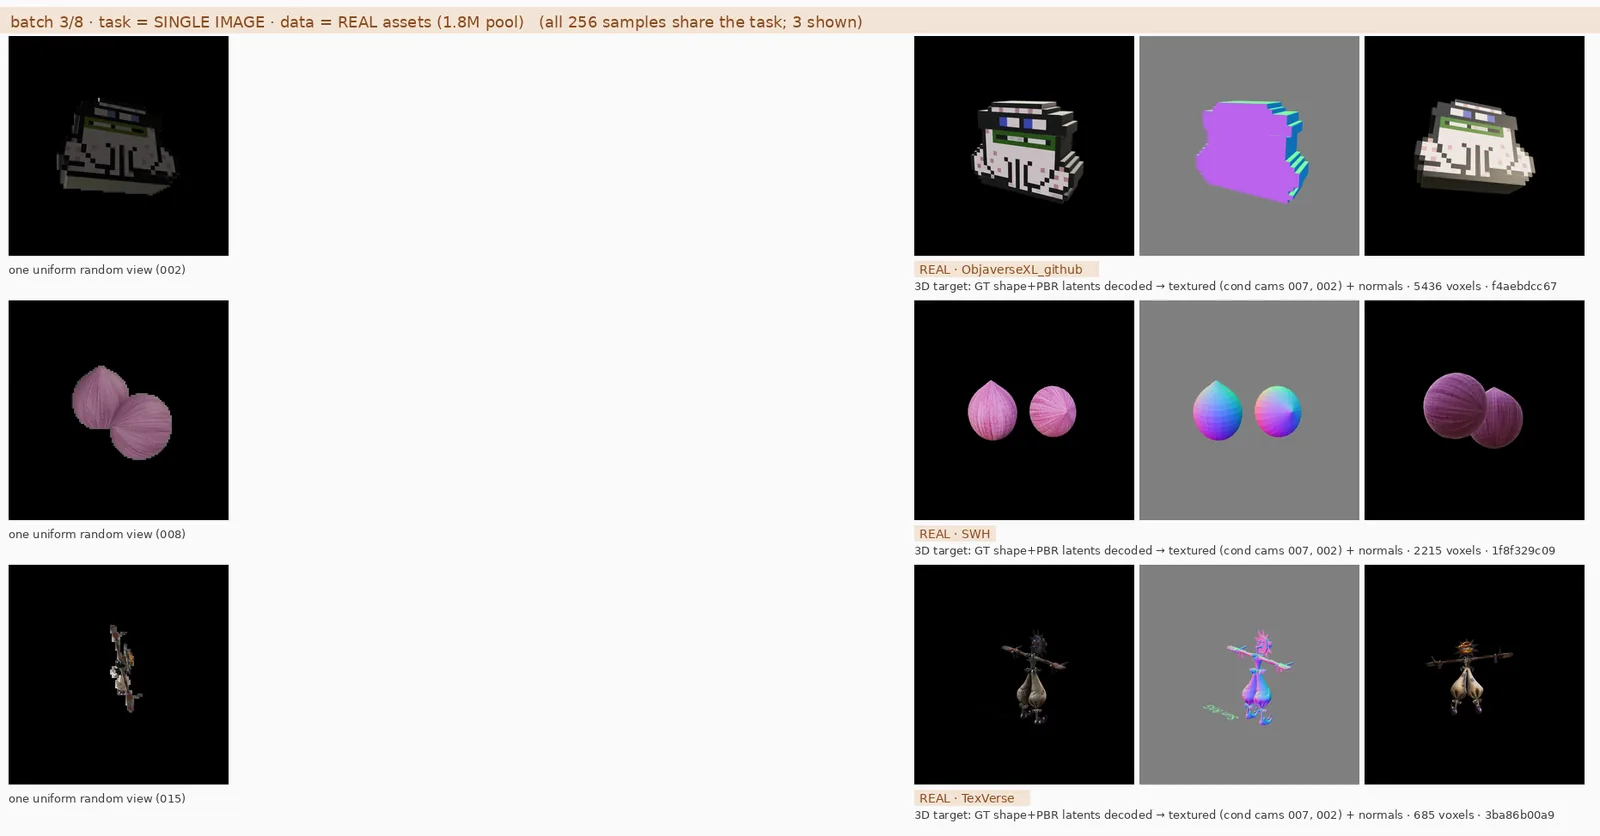
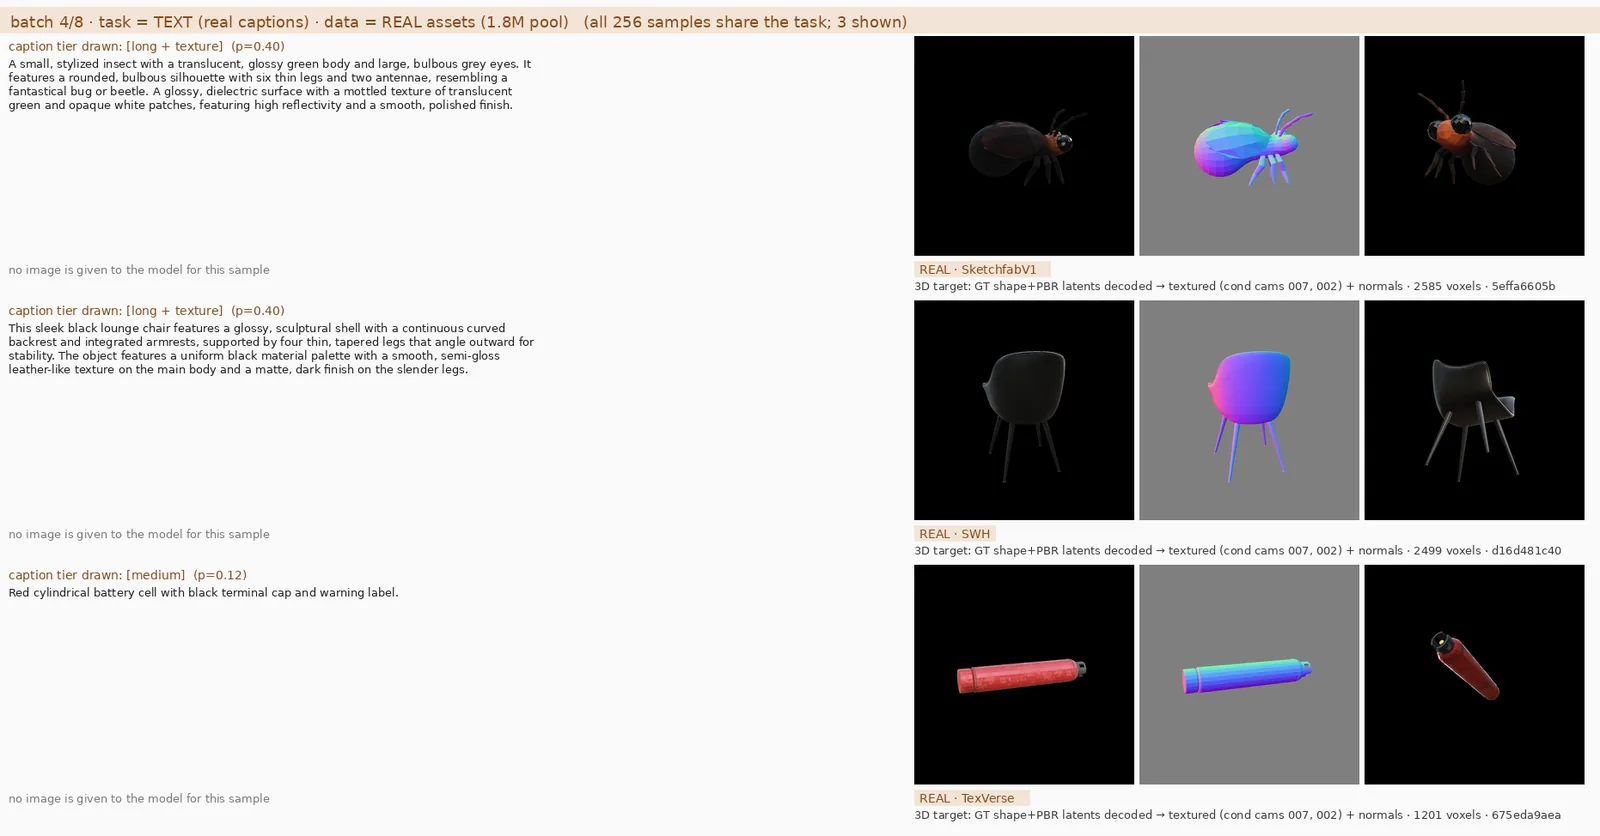
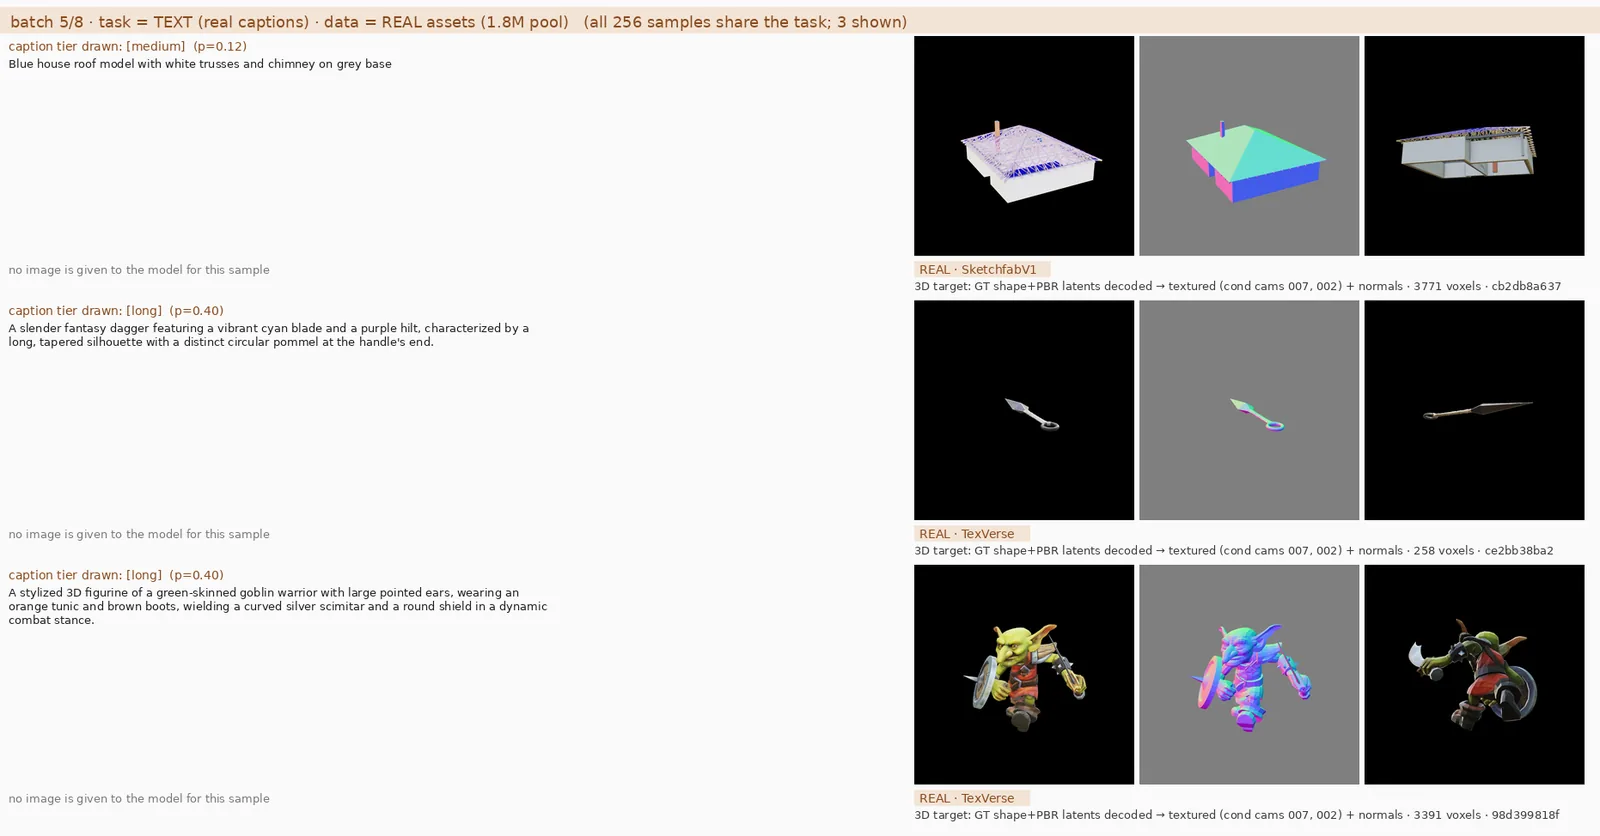
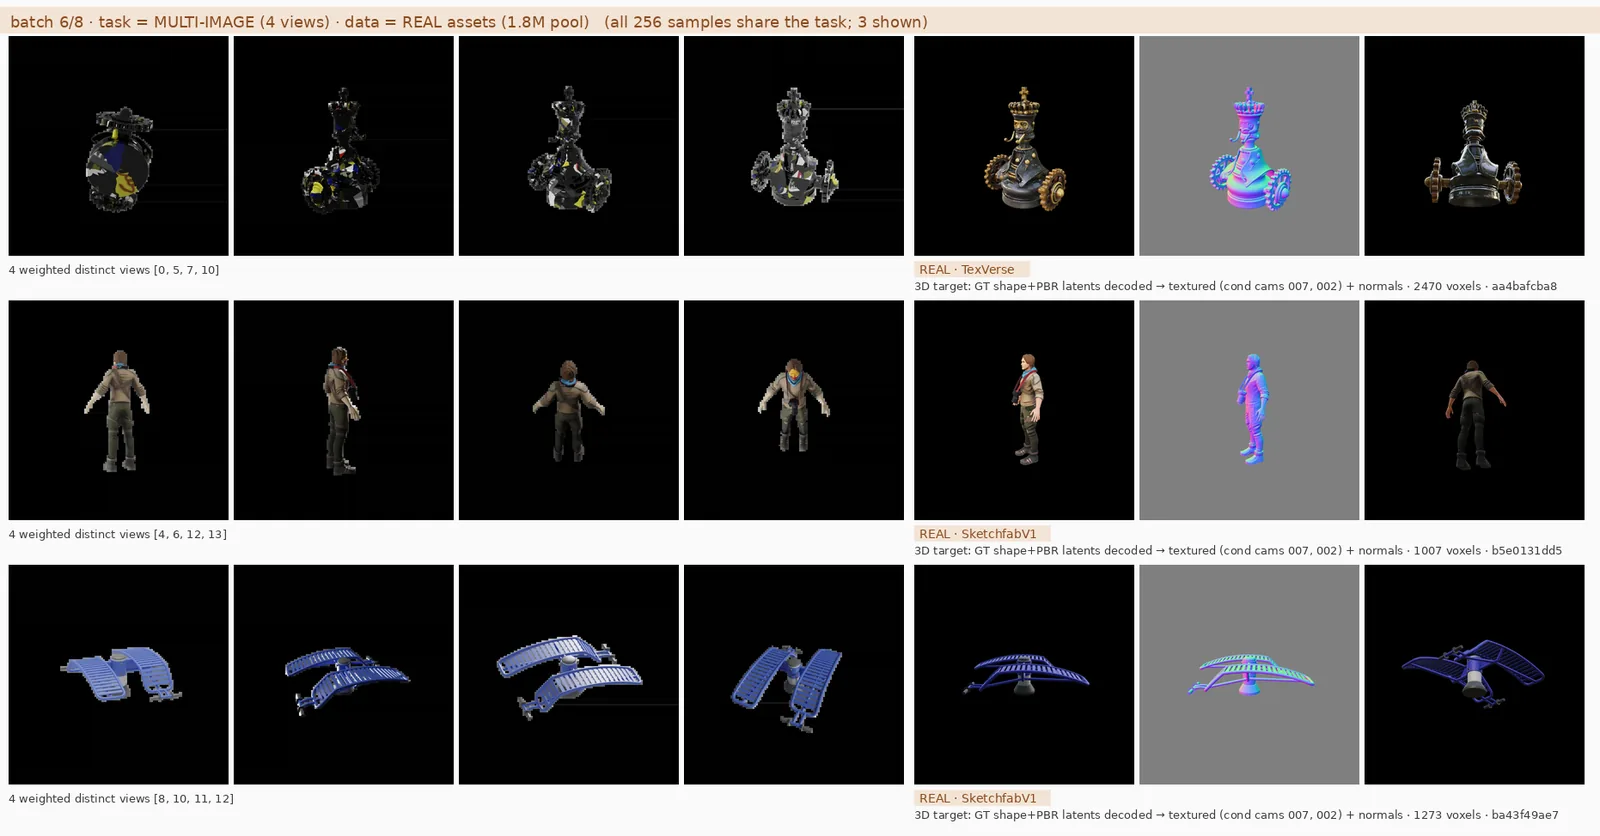
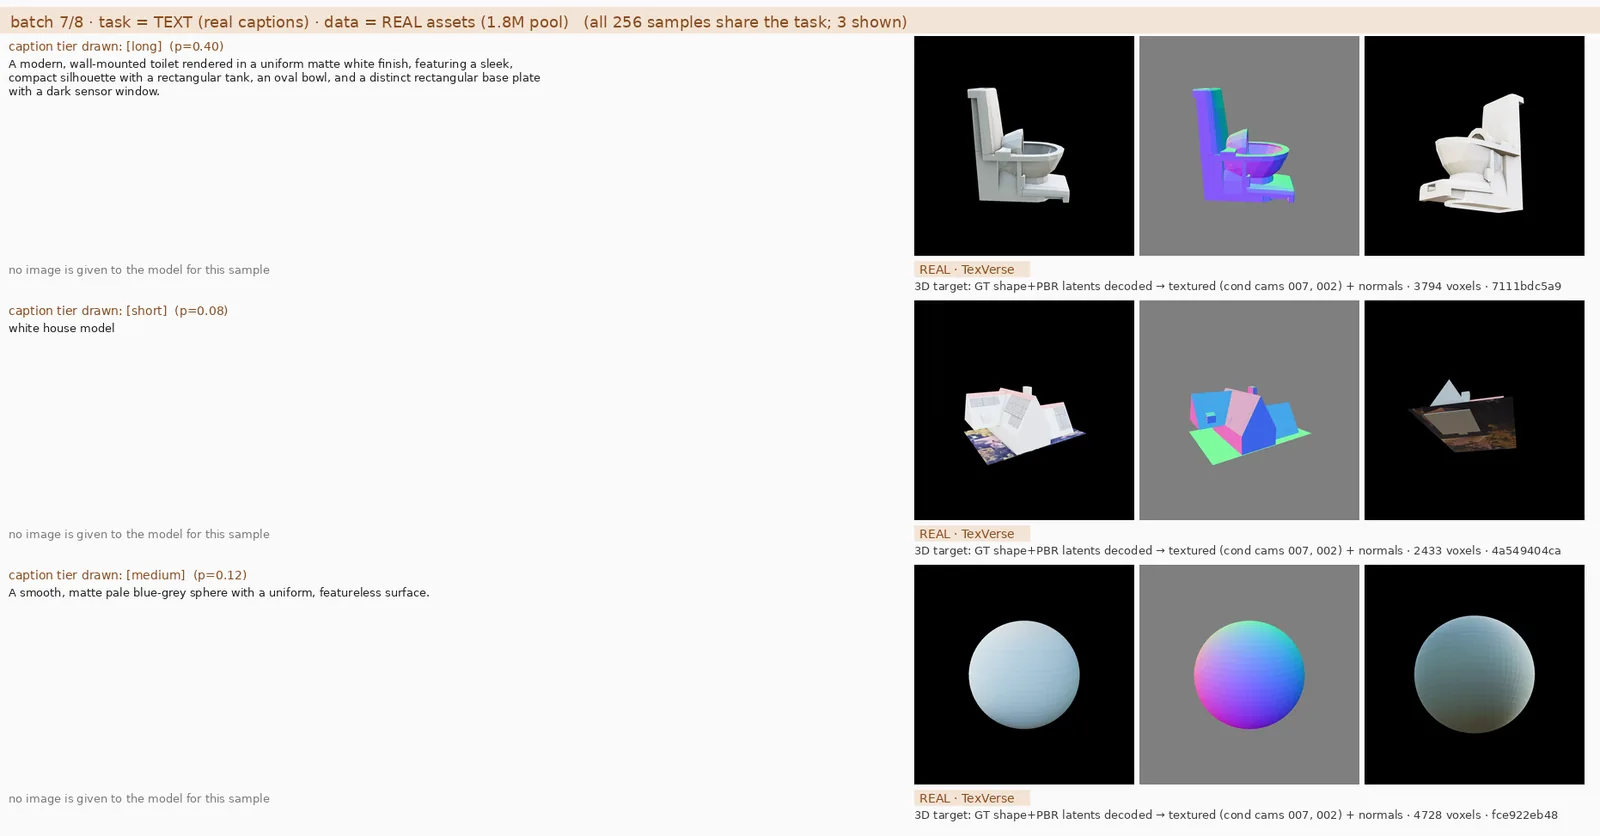
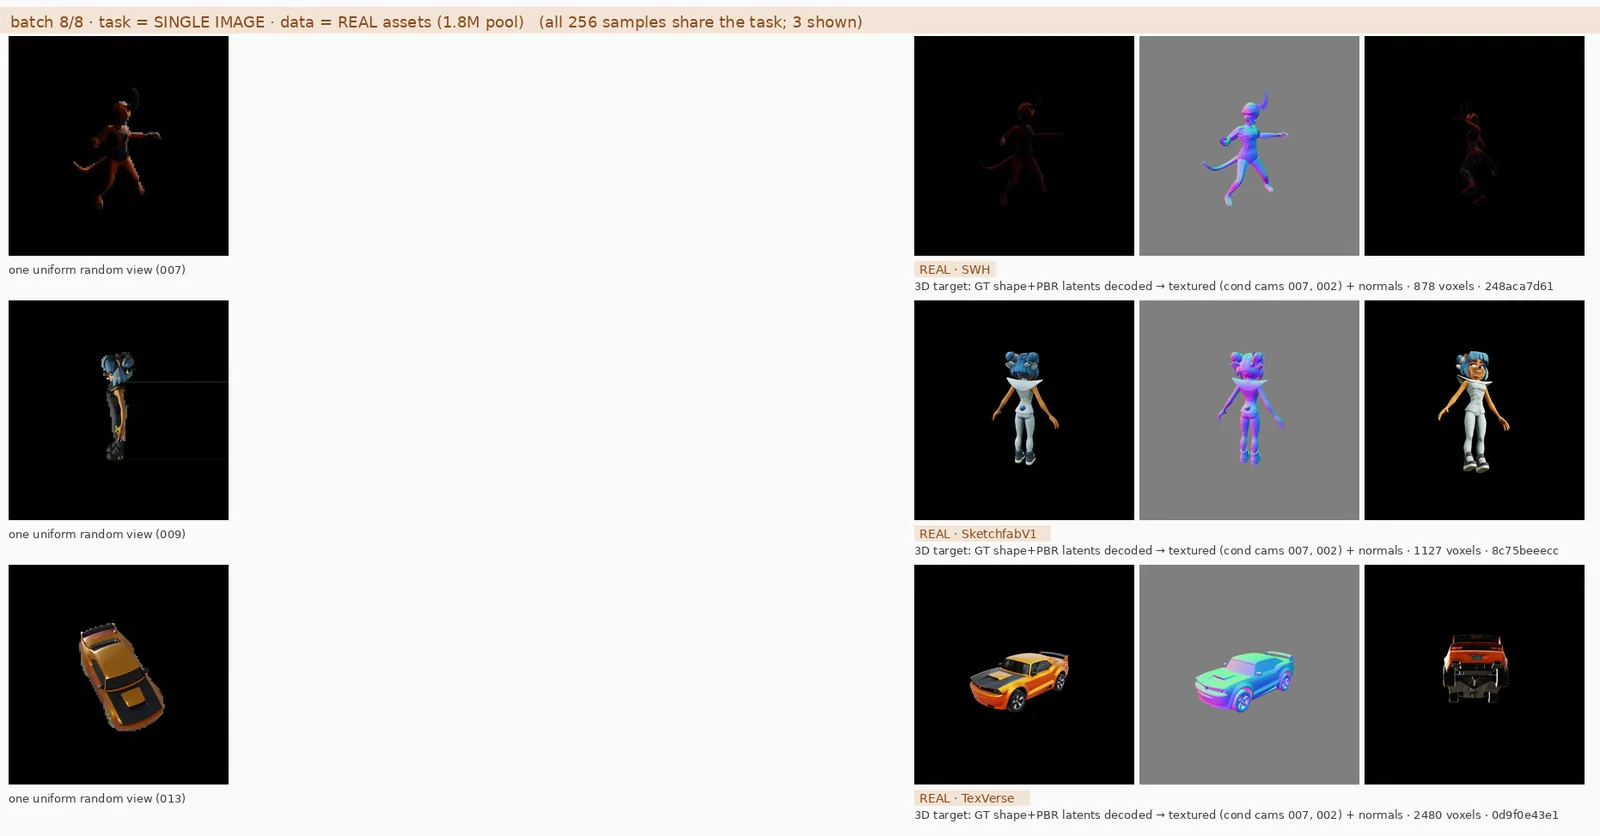
Eight consecutive batches drawn by the v12 batch-level sampler (SS mixture 0.60 / 0.10 / 0.15 / 0.15); every one of the 256 samples in a batch shares the task, 3 samples shown per batch.
Left = exactly what the model is conditioned on: the drawn caption tier (text tasks; no image is given, the synthetic gen image is shown greyed for reference only), one uniform random view (single image), or 4 weighted distinct views (multi-image).
Right = the 3D target: GT shape + PBR latents decoded by the frozen TRELLIS.2 decoders and rendered from the asset's cond cameras 007 and 002, plus the normal channel; voxel count and source subset in the caption.
Below-ground views (000-002) do show up in multi-image combos at their 0.15 weight (batch 2 row 3, batch 6 row 3).
batch 1/8 — condition (left) → decoded 3D target (right). Renders are 4× supersampled (1024 → 256); the left-hand conditioning views are the dataset's renders_cond files as stored.batch 2/8 — condition (left) → decoded 3D target (right). Renders are 4× supersampled (1024 → 256); the left-hand conditioning views are the dataset's renders_cond files as stored.batch 3/8 — condition (left) → decoded 3D target (right). Renders are 4× supersampled (1024 → 256); the left-hand conditioning views are the dataset's renders_cond files as stored.batch 4/8 — condition (left) → decoded 3D target (right). Renders are 4× supersampled (1024 → 256); the left-hand conditioning views are the dataset's renders_cond files as stored.batch 5/8 — condition (left) → decoded 3D target (right). Renders are 4× supersampled (1024 → 256); the left-hand conditioning views are the dataset's renders_cond files as stored.batch 6/8 — condition (left) → decoded 3D target (right). Renders are 4× supersampled (1024 → 256); the left-hand conditioning views are the dataset's renders_cond files as stored.batch 7/8 — condition (left) → decoded 3D target (right). Renders are 4× supersampled (1024 → 256); the left-hand conditioning views are the dataset's renders_cond files as stored.batch 8/8 — condition (left) → decoded 3D target (right). Renders are 4× supersampled (1024 → 256); the left-hand conditioning views are the dataset's renders_cond files as stored.
Composition by source subset. TexVerse + SWH + SketchfabV1 carry 78% of the 1.8M pool; the PBR-only 800k pool is SWH-heavy (45%).
2 · v12 task mixture and caption tiers
Batch-level sampling (granularity: batch, temperature 1): each optimizer step draws one task for the whole 256-batch.
Real-caption task = text_to_3d_weighted, synthetic = text_to_3d; both take caption_weights over the fixed caption order [long, medium, short, long + texture], renormalised over the captions an asset actually has (verified by 3,000-draw sampling test: observed within ±1.5% of target).
tier
real: weight
real: median words
synthetic: weight
synthetic: median words
long
0.40
31
0.45
25
medium
0.12
11
0.15
9
short
0.08
3
0.15
4
long + texture
0.40
54
0.25
31
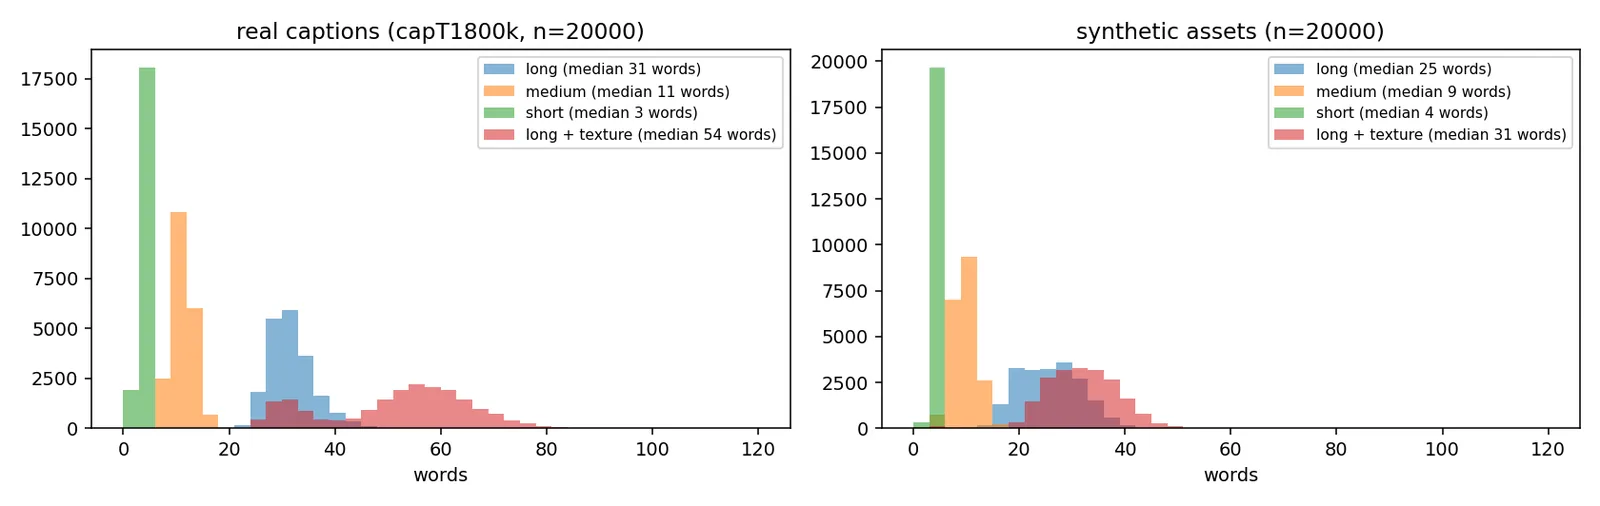
Left: identical 70/15/15 mixture for SS, shape and tex. Right: caption-tier weights; real captions lean on the two long tiers (80%), synthetic keeps 30% short/medium.Caption length by tier (words). Real long+texture captions run ~54 words median; synthetic tiers are shorter (25 / 9 / 4 / 31).
3 · Multi-image task: view sampling
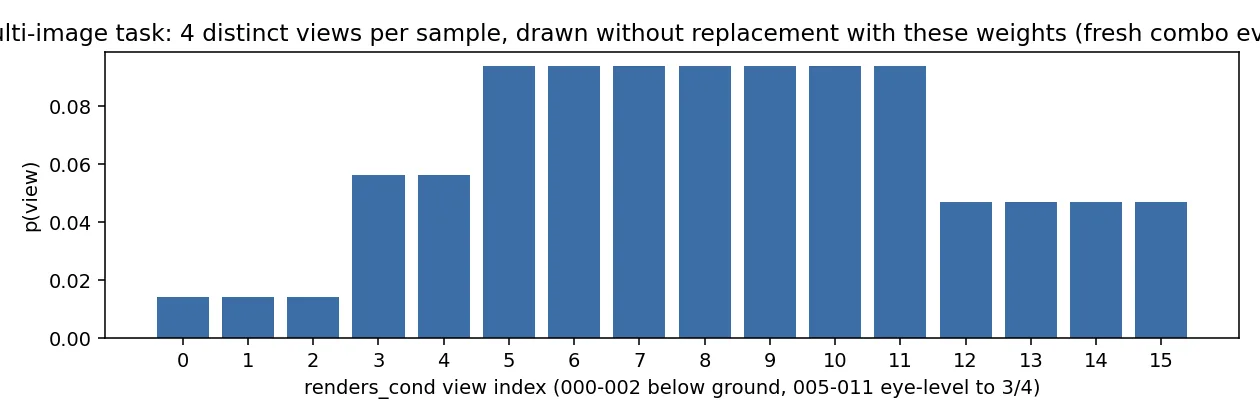
Live conditioning draws 4 distinct views per sample (IM_N_VIEWS = 4) with elevation-dependent weights; a fresh combo every draw (the old cache froze one combo per asset).
Below-ground views keep weight 0.15 each — they do appear in combos (see samples). Whether to lower them is a data-side knob.
Cost: a 4-view Qwen condition is ~8k tokens, 1.5-2× a single-image sample; at 15% share the mixture step time rises ~10%.
Per-view draw probability over the 16 renders_cond views.
4 · Samples per task
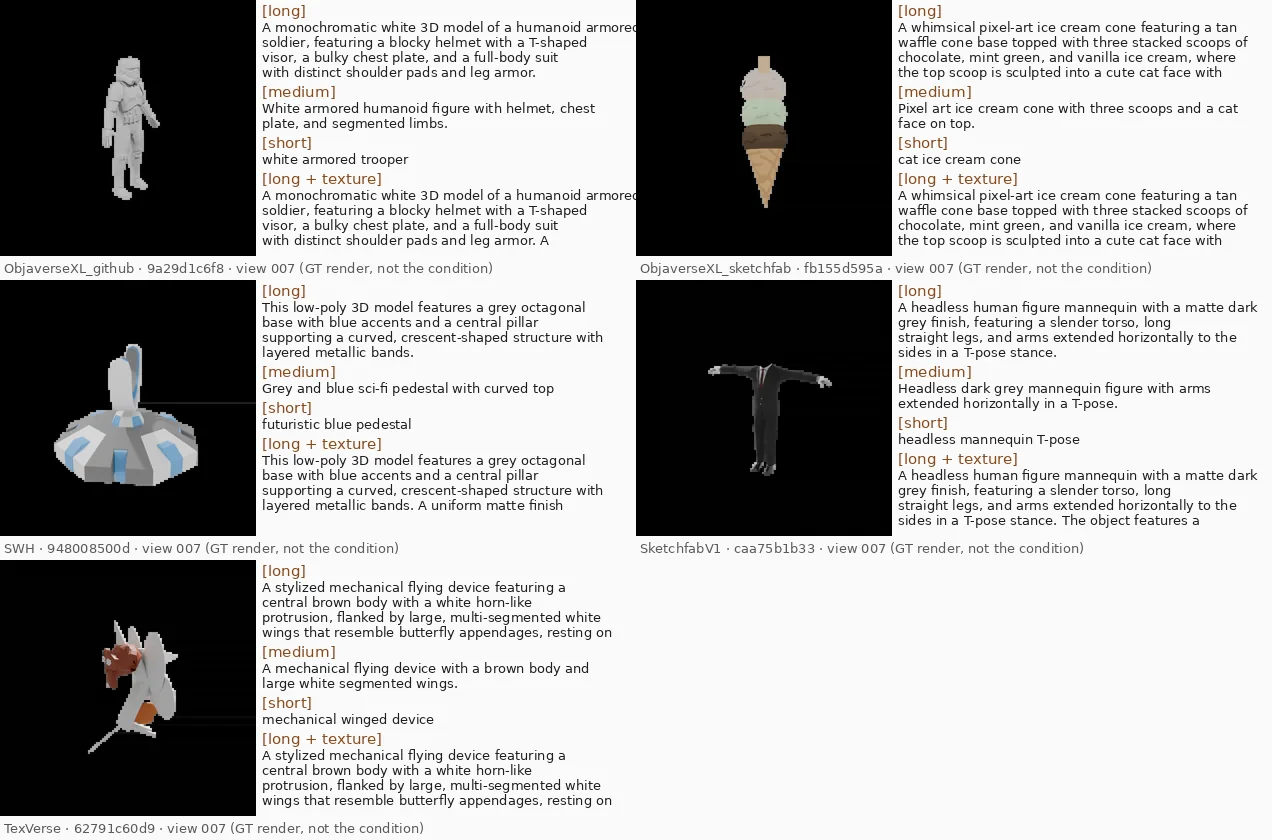
Text task: the four caption tiers of one asset; the render is the GT view 007, shown for reference only (text conditioning sees no image).
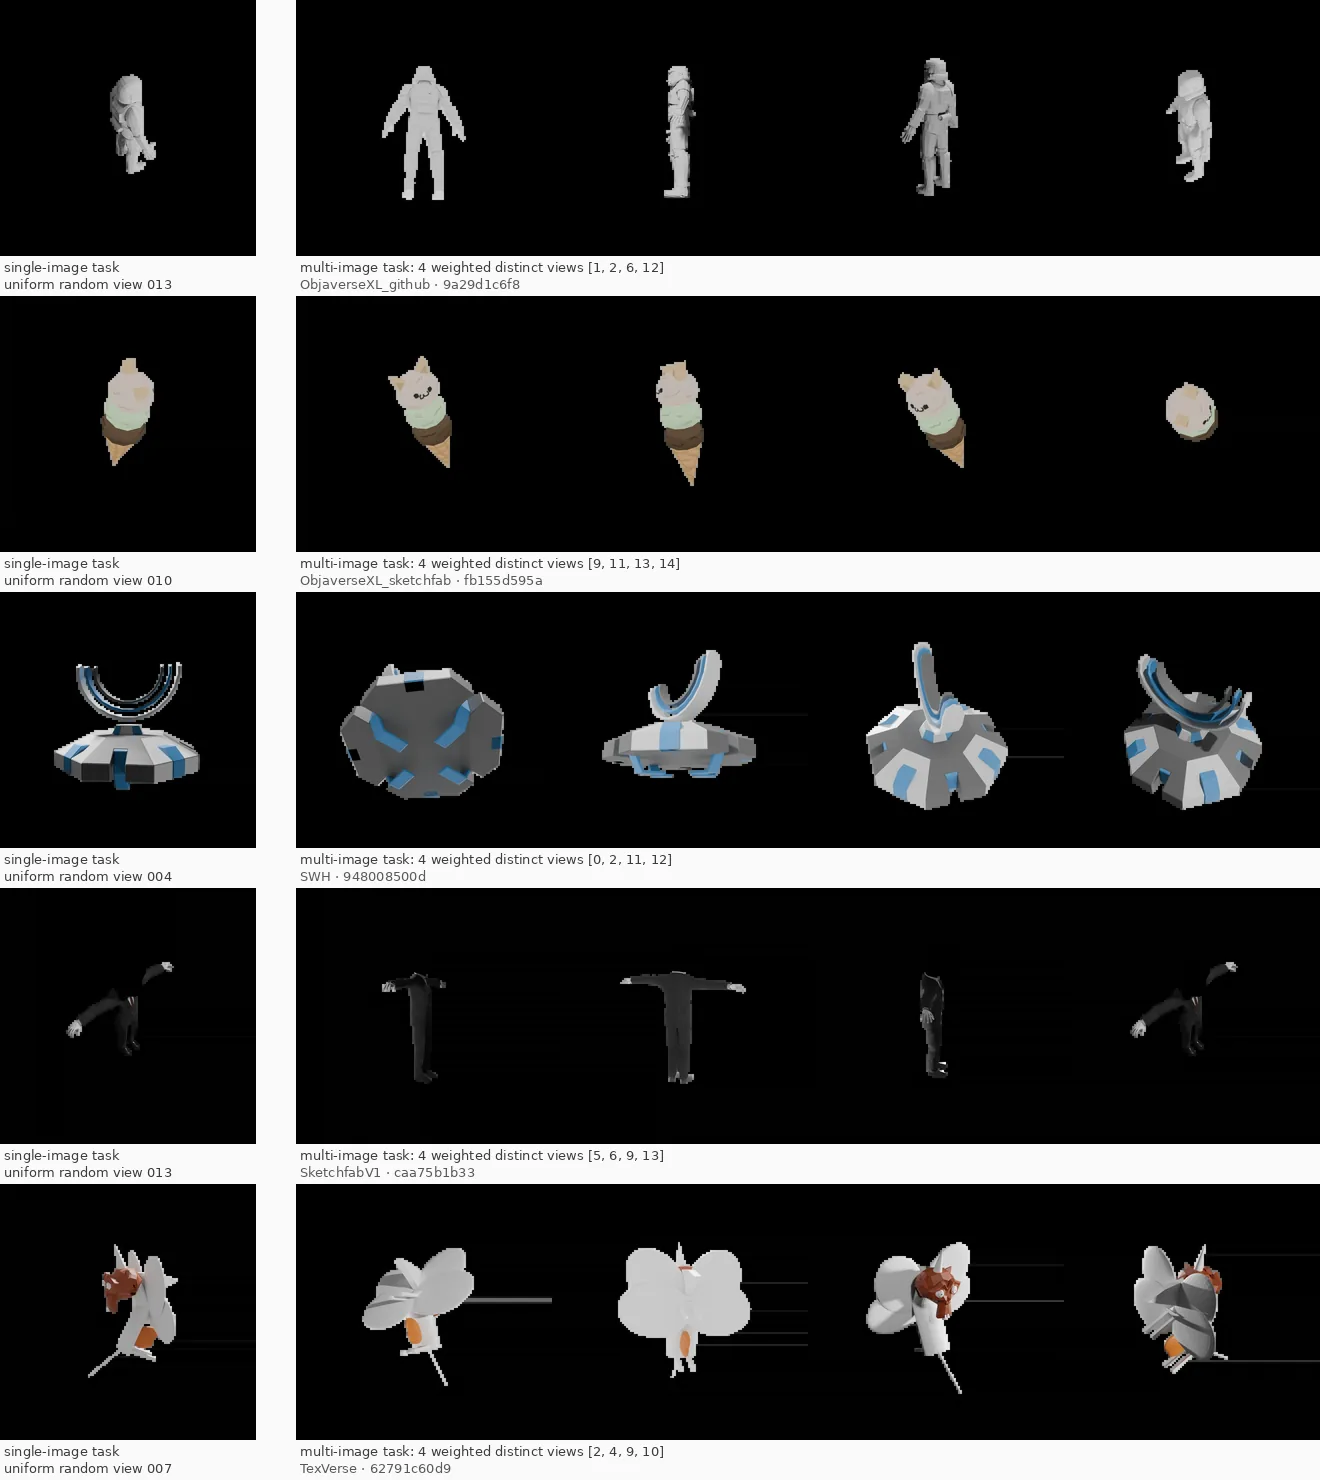
Single-image task: one uniform random view. Multi-image task: 4 weighted distinct views of the same asset.
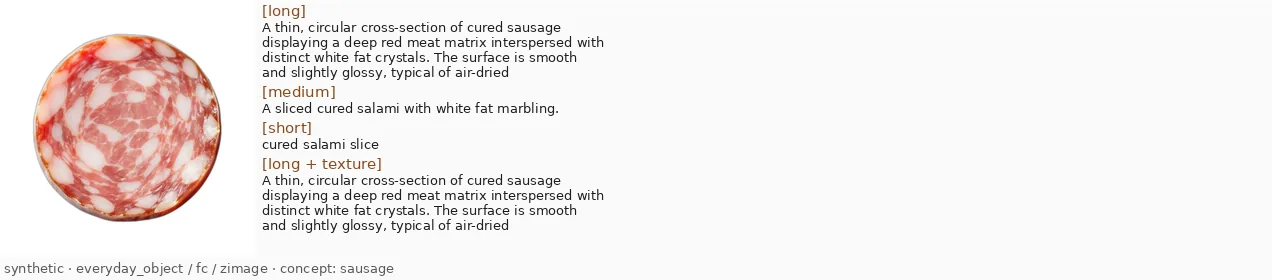
Synthetic assets: the text-to-image generation that was reconstructed into latents, with its caption tiers and coverage tags.
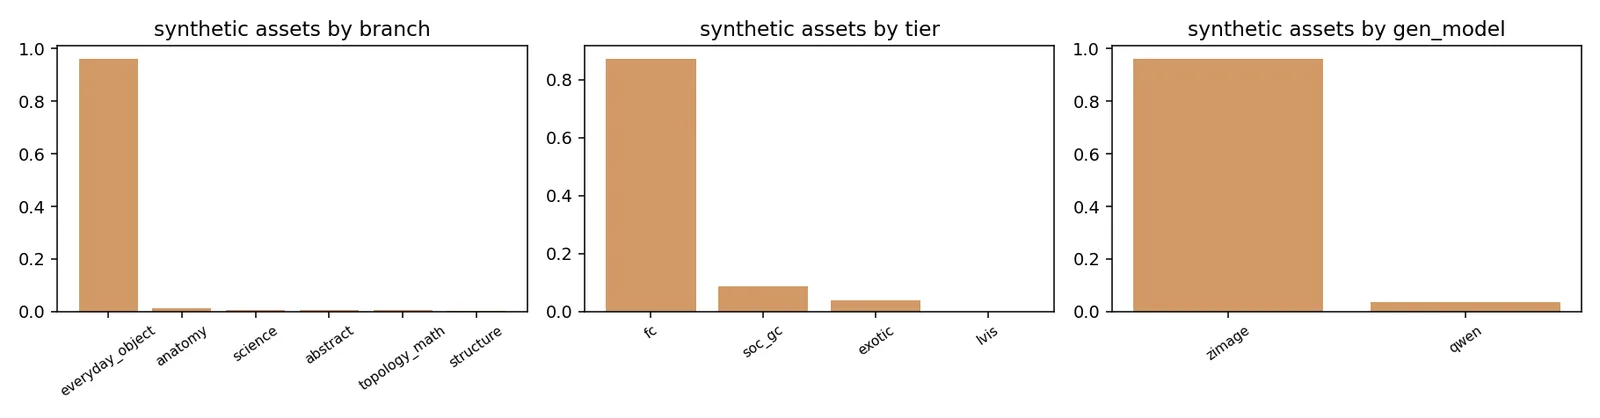
Text-to-3D samples (real captions): long / medium / short / long+texture tiers.Same assets as image-to-3D (left, one random view) and multi-image-to-3D (right, 4 weighted views).Synthetic coverage assets: generated conditioning image + caption tiers (branch / tier / generator).Synthetic pool composition: 96% everyday objects from zimage; the hard-concept branches (topology, anatomy, science) are small in count but are the reason the pool exists.
5 · Open questions
Real : synthetic ratio (6 : 1 committed vs 3 : 1 in roadv1).
Multi-image: fixed 4 views vs 2-4; below-ground view weight.
New held-out manifest from md5-rule sketchfab_test200 still recommended for the formal v12 tables (SWH stays for baseline comparability).
auto-generated from manifests/splits/*_evalclean.jsonl and configs/mix_v12_*.yaml · figures: _lc/data_report/make_figs.py